Taxonomic Profiling with Kraken2 and Bracken
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
Learning Objectives & Prerequisites
- Prerequisites: Complete command-line basics and understand that taxonomic databases define the scope of possible classifications.
- Objective: Classify shotgun metagenomic reads with Kraken2, estimate abundances with Bracken, and report database and contamination limitations.
- Expected Output: A taxonomic abundance table paired with the exact database version, read-processing choices, and interpretation caveats.
Suggested route: use the Bioinformatics Learning Path to review any prerequisite stage before continuing.
Taxonomic Profiling with Kraken2 and Bracken
Introduction
In shotgun metagenomics, one of the primary goals is answering: "Who is in this sample, and in what proportions?"
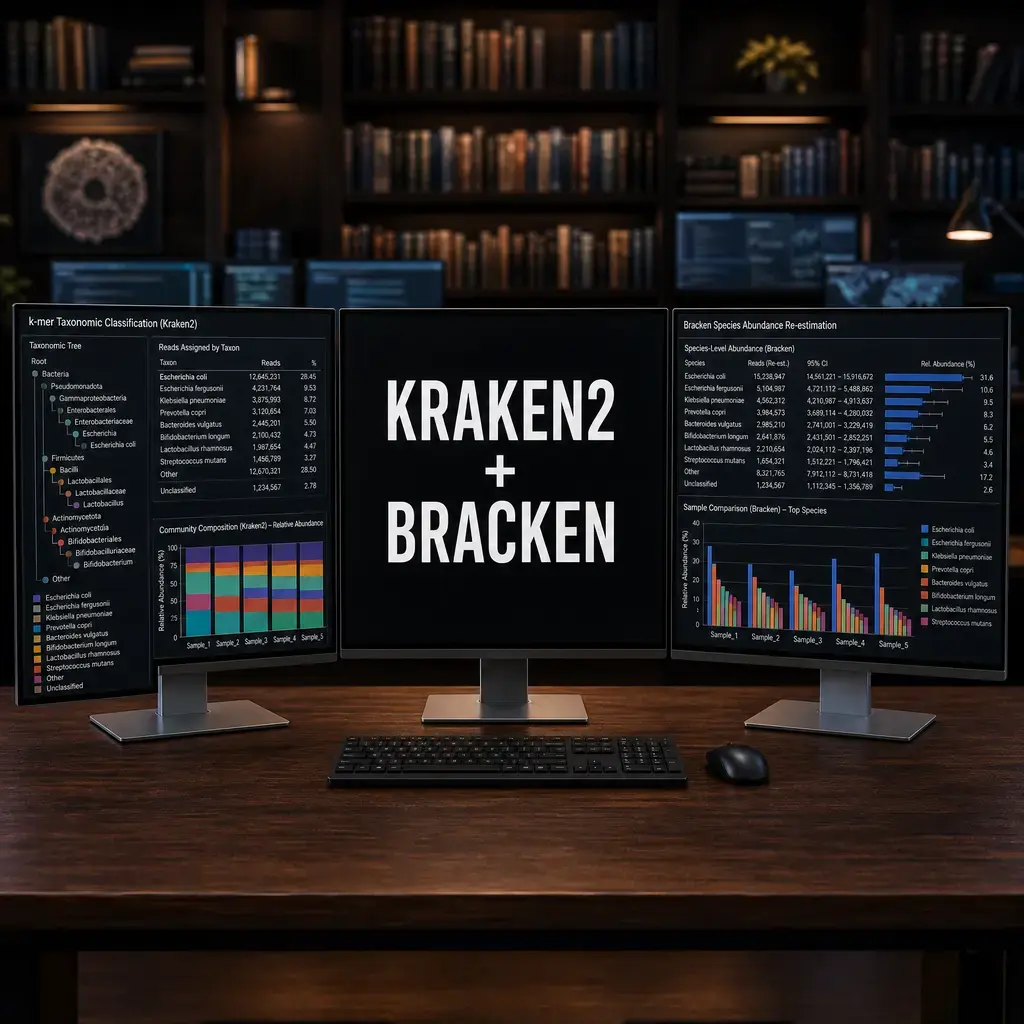
Unlike 16S amplicon sequencing, shotgun data contains fragmented DNA from every organism present. To classify millions of these short reads efficiently, we cannot use traditional alignment tools like BLAST - it would take months. Instead, we use ultra-fast k-mer based classifiers, with the undisputed industry standard being Kraken2, followed by Bracken for abundance estimation.
1. How Kraken2 Works
Kraken2 breaks down your reads into short sequences called k-mers (typically 35-mers). It then compares these k-mers against a massive pre-built database of known genomes.
Instead of full alignment, Kraken2 maps the k-mer to the Lowest Common Ancestor (LCA) in the taxonomic tree.
Running Kraken2
Kraken2 is heavily memory-bound. You need a machine with enough RAM to hold the database you choose (the standard PlusPFP database requires ~50GB of RAM).
# Run Kraken2 on paired-end Illumina reads
kraken2 --db /path/to/kraken2_database/ \
        --threads 16 \
        --paired reads_1.fastq.gz reads_2.fastq.gz \
        --report kraken2_report.txt \
        --output kraken2_output.txt
Key Outputs:
* kraken2_output.txt: Contains the classification for every single read.
* kraken2_report.txt: A human-readable summary of the percentage of reads assigned to each taxonomic level.
2. Correcting Abundances with Bracken
While Kraken2 is excellent at classification, its Lowest Common Ancestor (LCA) approach causes a problem: many reads are classified at higher taxonomic levels (like Genus or Family) because they match multiple species equally well.
This means your raw Species-level counts in Kraken2 are mathematically underestimated.
Bracken (Bayesian Reestimation of Abundance with KrakEN) fixes this. It uses Bayesian probabilities to accurately push those Genus-level assignments down to the Species level, giving you highly accurate abundance estimations.
Running Bracken
# Run Bracken using the Kraken2 report to estimate Species level (-l S) abundances
bracken -d /path/to/kraken2_database/ \
        -i kraken2_report.txt \
        -o bracken_species_abundances.tsv \
        -r 150 \
        -l S
(Note: -r 150 should match your Illumina read length).
3. Visualization
Once you have your Bracken outputs across multiple samples, you can merge them and visualize the community composition.
Tools like Krona create beautiful interactive HTML pie charts from Kraken2/Bracken reports.
# Install Krona tools
mamba install -c bioconda krona

# Generate an interactive Krona plot from the Kraken2 report
ktImportText kraken2_report.txt -o krona_visualization.html
By combining the blazing speed of Kraken2 with the statistical rigor of Bracken, you can profile complex microbial communities in minutes rather than months.
Understanding Taxonomic Profiling at Scale
Shotgun metagenomic sequencing generates millions of short reads from every organism present in a sample. The central challenge is assigning each read to a taxon quickly and accurately enough to be useful at typical sequencing depths. Kraken2 solves this using exact k-mer matching against a prebuilt reference database. For each read, it queries every k-mer and records which taxon, or set of taxa, contains that k-mer in the database. The taxon with the most k-mer matches is assigned as the classification.
This approach is extremely fast because the database lookup is essentially a hash table query. Kraken2 can classify hundreds of millions of reads per hour on a single node, which is roughly 10 to 100 times faster than alignment-based tools like Centrifuge or MetaPhlAn3 on large inputs. The trade-off is precision at the strain level: when two closely related strains share most of their k-mers, Kraken2 assigns reads to their lowest common ancestor rather than guessing a strain.
Why Bracken Is Necessary After Kraken2
A common misconception is that the read counts Kraken2 produces are already abundance estimates. They are not. Kraken2 reports how many reads were classified at each node in the taxonomic tree, including reads that could not be resolved below genus or family. A species in your sample may have very few reads reported at its own level because most of its reads were pulled up to the genus or even phylum level due to shared k-mers with relatives.
Bracken corrects for this by redistributing reads from higher-level nodes back down to species or genus level using a Bayesian model trained on the same database. For each node in the tree, Bracken estimates what fraction of reads that landed there should have been assigned to each child node, based on the expected read length and k-mer distribution. The result is a corrected abundance table where each species or genus has a realistic estimate of its relative contribution to the sample.
Database Choice Has a Larger Effect Than Most People Expect
One of the strongest determinants of classification accuracy is the reference database used. If an organism is not represented in the database, every read from it will be classified as unclassified. In gut microbiome samples, for example, unclassified reads can constitute 30 to 70 percent of the total depending on the database completeness. The standard Kraken2 database built from RefSeq may miss many gut-specific or environmental strains that have been sequenced more recently.
For most projects, the recommended approach is to build a custom database that includes NCBI RefSeq bacteria, archaea, and viruses plus the human genome for host removal, supplemented with any domain-specific sequences relevant to your samples. Database construction is time-consuming and memory-intensive, but it is a one-time cost that pays off across many projects.
Interpreting Relative Abundance: What the Numbers Actually Mean
Relative abundance data from Kraken2 and Bracken describe the composition of the sequenced library, not necessarily the true microbial community. DNA extraction efficiency, PCR amplification bias, read length, and library preparation all introduce systematic distortions. Two organisms present at equal true abundance may show a 10-fold difference in estimated abundance if their DNA extracts differently or if their GC content causes differential amplification.
This means that relative abundance comparisons within a sample are more reliable than absolute abundance comparisons across samples, and that cross-study comparisons require careful normalisation and ideally a shared reference mock community. When reporting results, describe what your abundance estimates represent and acknowledge the key sources of technical variation in your sample preparation workflow.
Key Decision Points Before Running Your Analysis
- Select a database that covers the organisms you expect in your samples, not just the standard RefSeq set.
- Set the Bracken read length to match your actual read length after trimming, not the sequencer nominal read length.
- Report confidence thresholds used for classification; the default 0.1 may need adjustment for your sample type.
- Always inspect the fraction of unclassified reads before interpreting composition results.
Knowledge Check & Assessment
1. Concept Verification
Why can a fast k-mer classification be confident yet still biologically wrong when the reference database is incomplete or contaminated?
2. Practical Execution
Run or inspect a Kraken2/Bracken result and identify the database version, assigned fraction, top taxa, and unclassified reads. Pass Criteria: Record the command or analysis choice, keep the output, and explain why it answers the stated task.
3. Troubleshooting
If unexpected taxa dominate a sample, how will you check negative controls, database composition, host contamination, and read quality?
Reviewed: July 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: Metagenomics