Text Processing
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
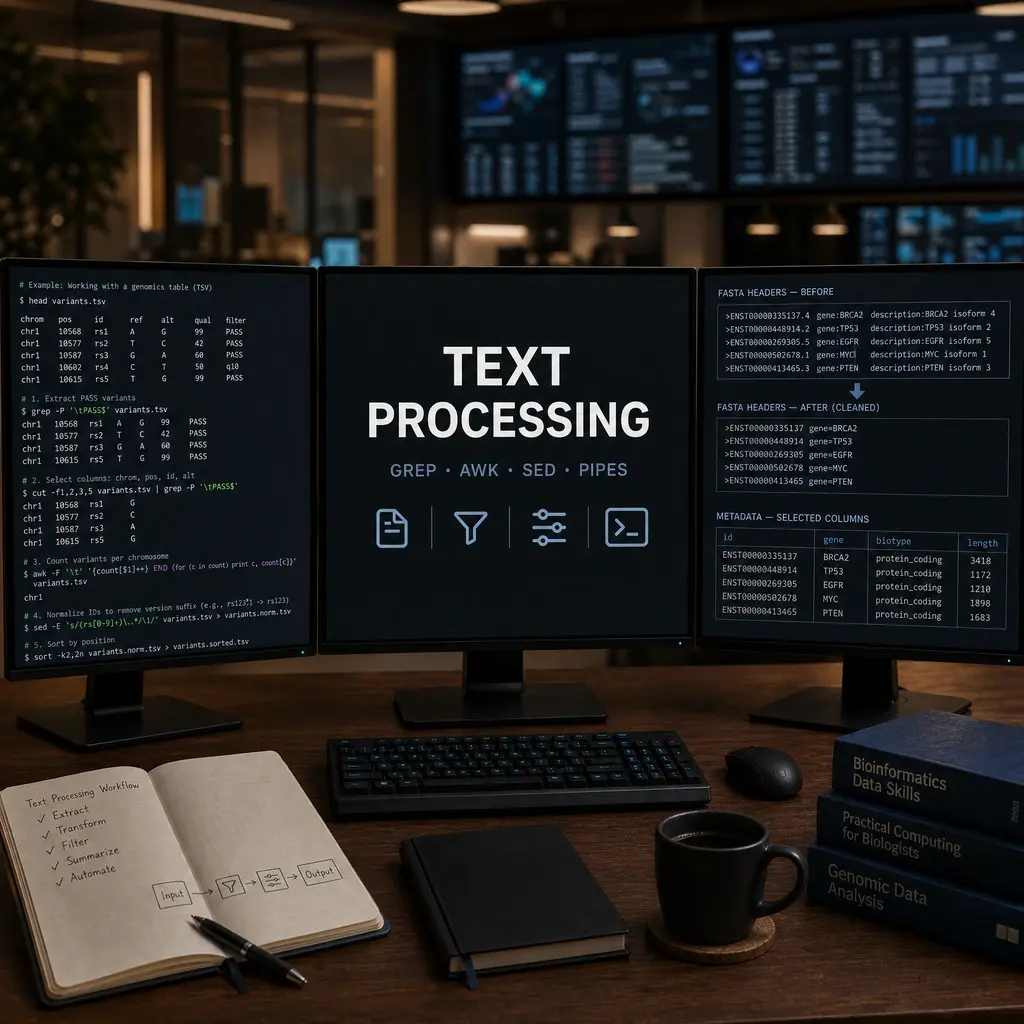
Learning Objectives & Prerequisites
- Prerequisites: Complete Basic Navigation and have example text, FASTA, or tab-delimited files available.
- Objective: Use grep, cut, sort, uniq, sed, and pipes to filter, summarize, and reshape biological text files.
- Expected Output: A reproducible one-line or small shell workflow that extracts and summarizes a defined set of records.
Suggested route: use the Bioinformatics Learning Path to review any prerequisite stage before continuing.
Text Processing: The Bioinformatician's Superpower
Viewing File Contents
cat - Display entire file
cat sequences.fasta             # Show entire file
cat file1.txt file2.txt        # Concatenate files
head - Show beginning of file
head sequences.fasta            # First 10 lines
head -n 20 sequences.fasta      # First 20 lines
head -n 5 *.txt                # First 5 lines of all text files
tail - Show end of file
tail sequences.fasta            # Last 10 lines
tail -n 20 sequences.fasta      # Last 20 lines
tail -f logfile.txt            # Follow file as it grows
less - Interactive file viewer
less sequences.fasta # View file interactively
Navigation in less:
- Space: Next page
- b: Previous page
- /pattern: Search forward
- q: Quit
Searching and Filtering (grep)
grep is arguably the most powerful text-searching tool in a bioinformatician's toolkit. Instead of manually scrolling through gigabytes of text, grep allows you to extract exactly the lines you need based on pattern matching. The name stands for "global regular expression print", which hints at its ability to use complex regular expressions, though simple string matching is often enough for daily tasks.
In bioinformatics, you will use grep constantly to extract specific sequences, find error messages in log files, or pull out records matching a specific gene ID. It is incredibly fast and memory-efficient because it processes files line-by-line rather than loading the entire file into RAM. Here are the most common usage patterns:
grep "ATCG" sequences.fasta      # Find lines containing ATCG
grep -c ">" sequences.fasta      # Count sequence headers
grep -v ">" sequences.fasta      # Show lines NOT containing >
grep -i "error" logfile.txt      # Case-insensitive search
grep -n "pattern" file.txt       # Show line numbers
grep -A 3 -B 3 "pattern" file    # Show 3 lines after and before
Counting Things (wc)
wc file.txt                      # Lines, words, characters
wc -l file.txt                   # Count lines only
wc -w file.txt                   # Count words only
wc -c file.txt                   # Count characters only
Sorting and Uniqueness
sort - Sort lines
sort file.txt                    # Sort alphabetically
sort -n numbers.txt              # Sort numerically
sort -r file.txt                 # Reverse sort
sort -k 2 data.txt              # Sort by second column
uniq - Remove duplicates
uniq file.txt                    # Remove adjacent duplicates
sort file.txt | uniq             # Remove all duplicates
uniq -c file.txt                 # Count occurrences
Bioinformatics-Specific Examples
Working with FASTA Files
Count sequences in a FASTA file
grep -c ">" sequences.fasta
Extract sequence headers
grep ">" sequences.fasta | head -10
Remove the ">" from headers
grep ">" sequences.fasta | sed 's/>//'
Find sequences with specific patterns
The quick grep -A 1 approach works only when each sequence occupies exactly one line. Many FASTA files wrap long sequences over multiple lines, so inspect the file with less sequences.fasta before using line-based commands.
For a wrapped or unknown FASTA layout, use a sequence-aware tool such as seqkit:
# Install once in a bioinformatics environment
mamba install -c conda-forge -c bioconda seqkit

# Search sequence content, then preserve complete FASTA records
seqkit grep -s -p "ATGC" sequences.fasta > matching_sequences.fasta
seqkit stats matching_sequences.fasta
The final seqkit stats command should report the number and lengths of the records retained.
Working with FASTQ Files
Count reads in a FASTQ file
wc -l reads.fastq | awk '{print $1/4}'
Extract quality scores
awk 'NR%4==0' reads.fastq | head -10
Convert FASTQ to FASTA
awk 'NR%4==1{printf ">%s\n", substr($0,2)} NR%4==2{print}' reads.fastq > sequences.fasta
Working with Tab-Delimited Files
View first few columns
cut -f 1,2,3 data.tsv | head
Sort by a specific column
sort -k 3 -n data.tsv # Sort by 3rd column numerically
Filter rows based on column values
awk '$3 > 100' data.tsv # Show rows where column 3 > 100
Knowledge Check & Assessment
1. Concept Verification
How do standard input, standard output, a pipe, and a redirect connect command-line tools?
2. Practical Execution
Use grep, cut, sort, and uniq to count a selected feature or sequence header from a supplied text file. Pass Criteria: Record the command or analysis choice, keep the output, and explain why it answers the stated task.
3. Troubleshooting
If a pipeline returns no records, how will you test each command separately and inspect quoting, delimiters, and regular expressions?
Reviewed: January 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: Shell Command Basics