HPC Troubleshooting and Support
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
Learning Objectives & Prerequisites
- Prerequisites: Complete the preceding HPC lessons and have access to your own job IDs and log files, where permitted.
- Objective: Diagnose common cluster problems, collect useful evidence, and write an effective support request without exposing sensitive data.
- Expected Output: A support-ready issue report containing the job ID, command, resource request, relevant log excerpt, and steps already attempted.
Suggested route: use the Bioinformatics Learning Path to review any prerequisite stage before continuing.
Diagnosing HPC Failures
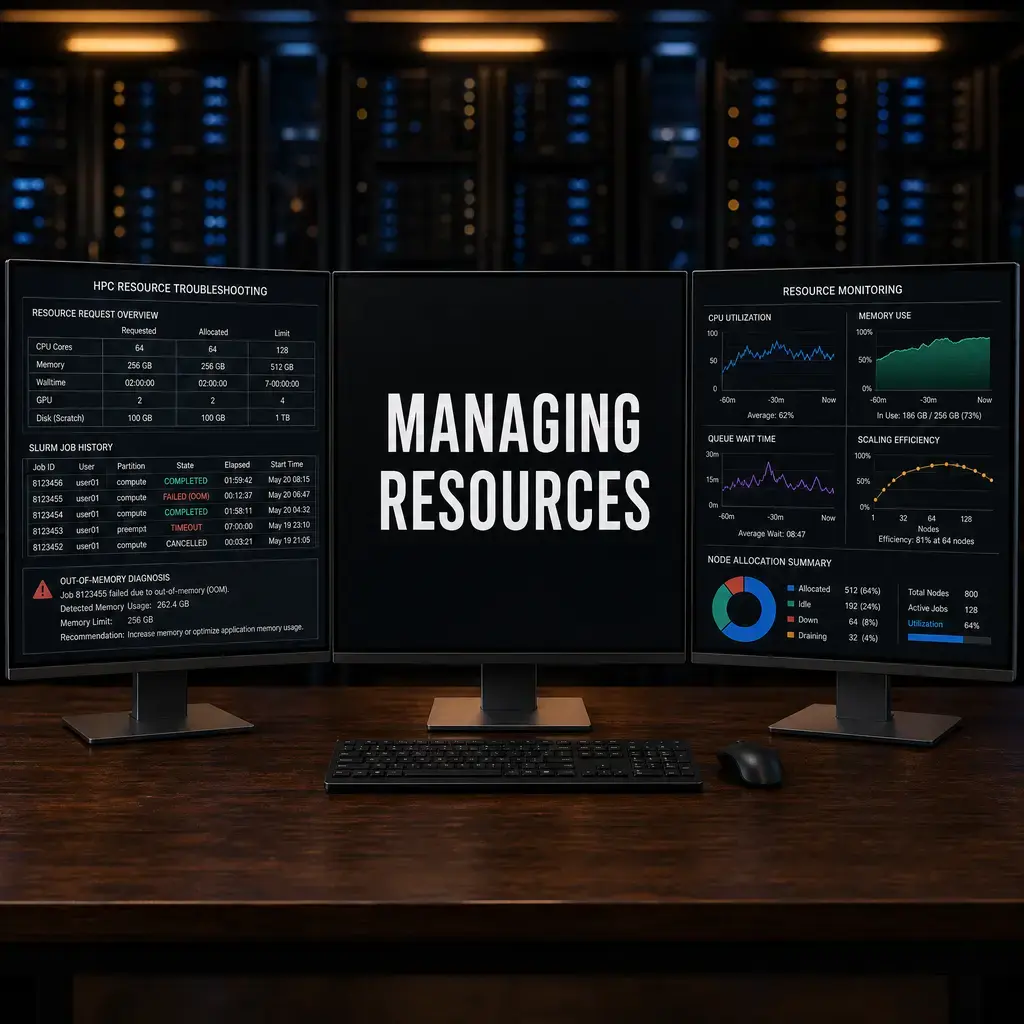
When running large-scale bioinformatics pipelines on a High-Performance Computing (HPC) cluster, job failures are inevitable. Whether it is an Out-Of-Memory (OOM) error, a timeout, or a missing dependency, knowing how to independently diagnose the issue is a critical skill.
Before escalating an issue to your cluster's support team or system administrators, you should systematically investigate the failure using Slurm's built-in accounting and profiling tools.
1. Checking Job State and Exit Codes
When a job fails or disappears from the queue, your first step should be checking its final state and exit code using sacct (Slurm Accounting).
# Replace 1234567 with your actual job ID
sacct -j 1234567 --format=JobID,JobName,State,ExitCode,Elapsed,ReqMem,MaxRSS
Common Slurm States:
COMPLETED: The job finished successfully (ExitCode 0:0).FAILED: The job terminated with a non-zero exit code. Look at theExitCodecolumn.TIMEOUT: The job exceeded its requested walltime (--time).OUT_OF_MEMORYorOOM: The job used more memory than requested (--mem).CANCELLED: The job was killed by the user or an administrator.
Understanding Exit Codes
If your job state is FAILED, the exit code provides the first clue:
* Exit Code 1: General error (e.g., syntax error in your script, file not found).
* Exit Code 127: "Command not found". This usually means you forgot to load a module (e.g., module load samtools) or activate your Conda environment before running the tool.
* Exit Code 137: Process killed (SIGKILL). In HPC environments, this is almost always an Out-Of-Memory (OOM) kill by the Linux kernel because your process exceeded the memory allocated to it by Slurm.
2. Investigating Out-Of-Memory (OOM) Errors
Memory limits are the most common cause of bioinformatics job failures. Tools like genome assemblers, aligners (STAR, BWA), and single-cell tools (Seurat, Scanpy) can consume massive amounts of RAM.
If you suspect an OOM error, compare the ReqMem (Requested Memory) with the MaxRSS (Maximum Resident Set Size, or peak memory usage) from your sacct output.
sacct -j 1234567 --format=JobID,ReqMem,MaxRSS,State
If MaxRSS is very close to or equals ReqMem, the job was killed for memory reasons.
Profiling with seff
Many clusters provide the seff (Slurm Efficiency) tool, which offers a highly readable summary of CPU and Memory utilization for a completed job.
seff 1234567
Output Example:
Job ID: 1234567
Cluster: omicshub-cluster
User/Group: TheOmicsHub/research
State: OUT_OF_MEMORY (exit code 125)
Nodes: 1
Cores per node: 8
CPU Utilized: 02:15:30
CPU Efficiency: 85.20% of 02:39:04 core-walltime
Job Wall-clock time: 00:19:53
Memory Utilized: 64.00 GB
Memory Efficiency: 100.00% of 64.00 GB
In this example, the memory efficiency is 100%, confirming the job hit its limit. The solution is to resubmit the job with a higher --mem request (e.g., --mem=128G).
3. Reading the Error Logs
Slurm normally writes standard output to slurm-<jobid>.out and standard error to the same file, unless you explicitly split them using --error=slurm-%j.err.
Always check the last 50 lines of your log file for stack traces or error messages from the software itself:
tail -n 50 slurm-1234567.out
Common log file errors:
* FileNotFoundError: No such file or directory: 'data/reads.fastq': Your script is running from the wrong directory. Ensure your submission script uses cd $SLURM_SUBMIT_DIR.
* ModuleNotFoundError: No module named 'scanpy': Your Conda environment wasn't activated in the batch script.
4. How to Write an Effective Support Ticket
If you have checked the exit codes, analyzed the logs, and still cannot resolve the issue, it is time to contact HPC support.
System administrators handle hundreds of users and tickets. A vague message like "My job failed, please help" will significantly delay your resolution. Instead, provide a Minimal Reproducible Example (MRE).
Information to Include:
- Job ID(s) of the failed runs.
- The exact command or submission script you used (
sbatch run_pipeline.sh). - The path to your working directory so admins can inspect the files.
- A specific excerpt of the error log (do not attach a 50MB log file; paste the relevant 20 lines).
- What you have already tried (e.g., "I increased the memory to 128G but it still failed with Exit Code 137").
Template for HPC Support:
Subject: Job failing with Exit Code 137 on the highmem partition
Hello HPC Support,
My job (
ID: 1234567) runningcellranger countfailed on thehighmempartition.
- Working Directory:
/scratch/users/TheOmicsHub/project_x- Script:
run_cellranger.sh- Log File:
slurm-1234567.outThe
sacctoutput showsState: FAILEDandExitCode: 137. I initially requested 64GB of RAM and it failed, so I increased it to 128GB (Job ID: 1234568), but it still failed immediately.The end of the log file shows:
error: memory allocation failed. Is there a hard limit on memory per task on this partition, or could this be a node-specific hardware issue?Thank you.
Knowledge Check & Assessment
1. Concept Verification
Why is a reproducible minimal example more useful to HPC support than a vague statement that “the cluster failed”?
2. Practical Execution
Run the diagnostic commands (`sacct` and `seff`) in this lesson for one completed or test job and assemble a concise troubleshooting note. Pass Criteria: Record the command or analysis choice, keep the output, and explain why it answers the stated task.
3. Troubleshooting
If a job fails with `Exit Code 127`, what is the most likely problem with your submission script?
Reviewed: May 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: High-Performance Computing (HPC)