Writing Slurm Job Scripts
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
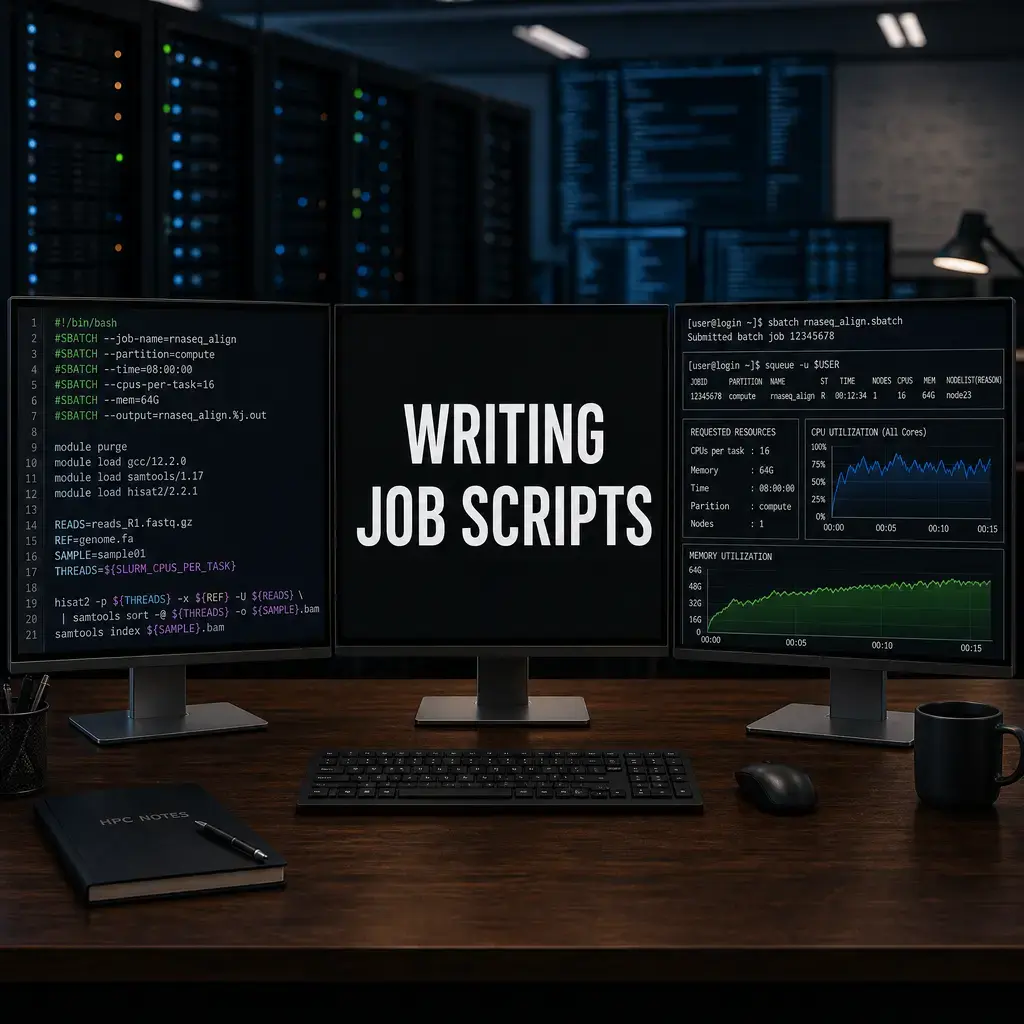
A Slurm submission script describes the resources a batch job requests and the commands it runs after the scheduler starts it. This walkthrough starts with a small smoke test; later optional examples cover task launches and arrays. Some optional examples use site-specific module names and partition values; confirm any such values with your cluster documentation before adapting or submitting those examples.
Format: Hands-on lab. With an authorized Slurm account and site-specific submission details, learners who have completed Basic Slurm Commands can adapt the harmless batch script, submit it, and inspect its log and final scheduler record. Without cluster access, use the planning check below to practise reading the script and distinguishing an accepted submission from a completed job.
Before you submit
- Complete the preceding Basic Slurm Commands lesson.
- Check your cluster's account, allowed partition, time limit, output-file location, and submission rules. Add an account directive only if your site requires one.
- Start with the harmless hostname/date smoke test below; do not substitute a research workload until you understand its input, resource, and storage requirements.
Deliverable: an adapted script, its submitted job ID, the log, and the final scheduler state. A job ID means Slurm accepted the submission; it does not mean the job started or completed.
Before you have cluster access
Hypothetical check: In the script below, which values must come from your cluster documentation, and what does a returned job ID establish? The partition and any required account or resource limits are site-specific; the example time and CPU values are illustrative. A returned ID means the scheduler accepted the submission, not that the job started or completed.
First job: a safe smoke test
This one-task example uses only hostname and date; it needs no biological data or software modules. Replace YOUR_ALLOWED_PARTITION with a partition confirmed in your site documentation (for example, use sinfo if your site permits it). Add an account directive only when local policy requires it. The short time limit and resource values are illustrative, not guarantees or universal defaults.
#!/bin/sh
#SBATCH --job-name=hpc-smoke
#SBATCH --ntasks=1
#SBATCH --cpus-per-task=1
#SBATCH --time=00:02:00
#SBATCH --partition=YOUR_ALLOWED_PARTITION
#SBATCH --output=hpc-smoke-%j.out

hostname
date
What the resource request means
--ntasks=1 requests one task (typically one process); --cpus-per-task=1 requests one CPU for that task. Neither directive makes an application multithreaded: a threaded program must also be configured according to its own documentation, and its thread count should fit the CPUs requested. Here the two simple diagnostic commands need no parallel configuration. A time limit and partition are site-policy choices; consult local documentation rather than copying another cluster's settings.
A few other details:
--job-namelabels the job in scheduler reports. Usesqueue -j JOB_IDto inspect a pending or running job.- Slurm substitutes
%jin the output filename with the job ID. The log is useful only if the chosen path is writable and visible as expected under your site's filesystem rules.
Slurm documents job environment variables individually; there is no general rule that uppercases every long option and transforms it into an environment-variable name. Examples in the official list include SLURM_JOB_ID, SLURM_JOB_NAME, and SLURM_SUBMIT_DIR. SLURM_NTASKS is set when --ntasks or an --ntasks-per-* option is specified; SLURM_CPUS_PER_TASK is set only when --cpus-per-task or --tres-per-task=cpu=# is specified; SLURM_ARRAY_TASK_ID is set for array tasks. SLURM_JOB_NODELIST describes nodes allocated to the job, so it is meaningful once an allocation exists. Names and conditions vary by variable: use the official sbatch output environment-variable list, not a guessed conversion. In shell code, a documented variable is expanded with a leading $.
Decomposing the script
A submission script is composed of the following parts:
- A shebang.
- Options.
- Comments.
- Shell commands.
- Run commands.
Shebang
The shebang is always the first line of the script. It specifies which shell interpreter to use for shell commands. Replace sh with whatever shell you want in the following line.
#!/bin/sh
Options
Options are lines that start with:
#SBATCH
They have two purposes:
-
The directives request resources:
--ntasksis the number of processes/tasks and--cpus-per-taskis CPUs per task. In the smoke test, one task times one CPU per task requests one CPU total; that script does not specify a memory amount. These are requests subject to site limits and scheduler configuration.Note: Allocating a lot of resources doesn't mean that all of them will be used. If a program is not configured for parallel execution, it will use one CPU even when more are allocated. Start with a documented estimate, run a small test, then inspect actual resource use with the scheduler rather than logging directly into a compute node. For example:
bash
squeue -j <job_id>                 # queue state
sstat -j <job_id>.batch --format=JobID,MaxRSS,AveCPU
sacct -j <job_id> --format=JobID,State,Elapsed,MaxRSS,AllocCPUS
If you need an interactive diagnostic session, request one through the scheduler, for example
srun --pty --cpus-per-task=2 --mem=8G --time=01:00:00 bashOnly SSH to a compute node when your own cluster documentation explicitly permits it.Actual CPU allocation and binding can differ with the cluster's select and task plugins, core/thread topology, and request options. Check the local documentation and the allocation reported for your job rather than assuming a fixed multiplier.
-
The directives configure the batch allocation. An
sruncommand launches a job step inside it; do not assume every batch option maps to a step option identically. Set step-level task or CPU counts explicitly when needed and check the Slurm documentation for the particular option.
There are many more options:
man sbatch
Slurm reads #SBATCH directives before the first non-comment, non-whitespace script line. Shell variables and expansions in those directive lines are not evaluated by the shell. To disable a directive, add another # so the line no longer begins with #SBATCH; for example, ##SBATCH --mem=2G is an ordinary shell comment, not a memory request.
##SBATCH --mem=2G
Shell commands
Shell commands are used to set up Linux environment variables. They should not be preceded by srun
Run commands
Use srun when launching a parallel job step so Slurm starts and tracks the task or tasks within the allocation. A serial command can sometimes run directly in the batch shell, but srun makes the step and requested task count explicit. Match task count and CPUs per task to the program's documented parallel model.
CPU threads and cluster policy
Slurm's CPU units, hardware threads, cores, and binding behavior depend on the site's configuration. A request for one CPU does not imply a universal number of physical cores or a fixed performance level. The optional --hint=nomultithread setting may be unsupported or may alter placement; use it only according to local guidance. For memory-per-CPU requests, verify how your cluster counts allocated CPUs and applies limits.
Optional advanced topic: parallel steps and arrays
Calling the same program multiple times in parallel
#!/bin/sh
#SBATCH --job-name example_script

#SBATCH --ntasks 3
#SBATCH --cpus-per-task 1
#SBATCH --mem 6G

#SBATCH --partition ibrain
#SBATCH --output %x-%j.out
#SBATCH --hint=nomultithread


module purge
module load gcc/7.3.1

srun program
Here the allocation requests three one-CPU tasks. A step that launches three tasks can start the executable three times, so use this pattern only when the program is designed for independent task launches (or is an MPI program configured for them). A single ordinary serial program may not use these resources as intended. Specify the step's task count explicitly, for example srun --ntasks=3 program, then follow the program's own parallelization instructions.
Several steps in parallel
Here is the full script.
#!/bin/sh
#SBATCH --job-name example_script

#SBATCH --ntasks 3
#SBATCH --cpus-per-task 1
#SBATCH --mem 6G

#SBATCH --partition ibrain
#SBATCH --output %x-%j.out
#SBATCH --hint=nomultithread


module purge
module load gcc/7.3.1

srun --ntasks=1 program0 &
step0_pid=$!
srun --ntasks=1 program1 &
step1_pid=$!
srun --ntasks=1 program2
step2_status=$?
wait "$step0_pid"
step0_status=$?
wait "$step1_pid"
step1_status=$?
if [ "$step0_status" -ne 0 ] || [ "$step1_status" -ne 0 ] || [ "$step2_status" -ne 0 ]; then
  echo "At least one parallel step failed (program0=$step0_status, program1=$step1_status, program2=$step2_status)." >&2
  exit 1
fi
This is an optional advanced pattern, not a first-job script. Each step requests one task so each command runs once; the shell records and waits for both background process IDs and checks the foreground command too. Any failed step makes the script exit nonzero instead of silently treating the final command's status as proof that all steps succeeded. Scheduling, site configuration, and program resource needs still matter. Use this only for independent work designed to run this way, and consult site and application guidance.
Arrays
A job array is useful for independent repetitions of the same script with an index-specific input or argument. The index values need not be consecutive; make sure your script maps every requested index to a valid input and that tasks do not overwrite one another's files.
#!/bin/sh
#SBATCH --job-name example_script

#SBATCH --array=0-2

#SBATCH --ntasks 1
#SBATCH --cpus-per-task 1
#SBATCH --mem 2G

#SBATCH --partition ibrain
#SBATCH --output %x-%A-%a.out
#SBATCH --hint=nomultithread


module purge
module load gcc/7.3.1

srun program --arg=$SLURM_ARRAY_TASK_ID
This array has task indices 0, 1, and 2. Slurm sets SLURM_ARRAY_TASK_ID to each task's index; %A and %a make the log name unique per array and task. Before scaling up, test the index-to-input mapping for the first, last, and an invalid index, and consider a concurrency cap such as --array=0-2%2 if the site permits it. Array scheduling order is not guaranteed.
Optional: running an interactive session
srun --pty --job-name interactive --partition ibrain --mem 2G --cpus-per-task 1 bash
srun --pty requests an interactive pseudo-terminal through Slurm; it may wait until requested resources become available. The final bash is the command started in that allocation. Use only resources and partitions allowed by local policy. A graphical session requires additional site support; do not assume replacing Bash with an application is sufficient.
Optional advanced topic: running a GUI with X11
srun --pty --job-name gui --partition ibrain --mem 2G --cpus-per-task 1 --x11 bash
--x11 requests X11 forwarding, which requires Slurm and the cluster's configuration to support it as well as a working local display setup. This command is not portable to every cluster. Follow site instructions for graphical applications, or use a supported remote visualization service.
Optional advanced topic: custom modules
Creating a custom module
If you have a program you want to make available to others, you can create a custom module for it. This involves creating a module file that defines the environment variables and paths needed to run your program.
Example module file (myprogram/1.0.lua):
help([[This module loads MyProgram version 1.0]])

prepend_path("PATH", "/path/to/myprogram/bin")
prepend_path("LD_LIBRARY_PATH", "/path/to/myprogram/lib")
This is a site-administered environment-modules example, not a complete user setup. Module systems differ; ask the cluster administrator how user modulefiles are enabled. The module use command adds a directory to the module search path; it does not simply print MODULEPATH.
Using a custom module
Once your custom module is created and placed in the correct location, you can load it like any other module:
module load myprogram/1.0
Optional advanced topic: Conda on a cluster
Installing Conda
Before installing software on a shared cluster, check whether the site permits user-managed Conda installations, where they may be stored, and whether downloads from external sites are allowed. Prefer the site's documented module or environment setup when provided. If local policy permits a personal installation, download the Miniconda installer and choose an approved location with sufficient space.
wget https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh
Follow the prompts during installation. When asked about initializing Conda, you can choose no if you prefer to activate it manually.
Using Conda Environments
After installation, you can create and manage Conda environments. This allows you to isolate different projects and their dependencies.
Create an environment:
conda create --name omics-r r-base
Activate an environment:
conda activate omics-r
Install packages:
conda install r-ggplot2
Deactivate an environment:
conda deactivate
The primary analysis example uses R. Python-based command-line tools can still require a Python runtime inside their own environment; that does not make Python a prerequisite for the R analysis. Inspect the solve plan before installing and record the actual package versions.
Conda in Submission Scripts
This example assumes Bash and a Conda installation at the placeholder path. Replace it with your actual installation and environment name. Some clusters provide Conda through a module or document another activation method; follow that site's instructions. Activation in a non-interactive batch shell must initialize the shell function before calling conda activate.
#!/bin/bash
#SBATCH --job-name conda_job
#SBATCH --ntasks 1
#SBATCH --cpus-per-task 1
#SBATCH --mem 4G
#SBATCH --partition ibrain
#SBATCH --output %x-%j.out

# Load Conda if not in PATH
# module load conda

# Activate your Conda environment
source /path/to/your/miniconda3/etc/profile.d/conda.sh
conda activate omics-r

# Run your reviewed R analysis script; this file is a placeholder, not supplied here.
srun Rscript --vanilla my_script.R

# Deactivate environment (optional, but good practice)
conda deactivate
Optional advanced topic: compression of files
Compression can reduce storage for some data, but it costs CPU time and can affect downstream tools. FASTQ files are often already gzip-compressed. Check the workflow's expected input format and storage policy before recompressing or deleting any source data.
Using gzip
gzip is a common compression utility. It replaces the original file with a compressed version (.gz extension).
Compress a disposable or backed-up file: by default gzip removes the original after creating the compressed file. Keep an independent copy if the source must be retained.
gzip my_file.txt
This will create my_file.txt.gz and remove my_file.txt
Decompress a file:
gunzip my_file.txt.gz
This will restore my_file.txt and remove my_file.txt.gz
Using tar with gzip (for directories)
To compress entire directories, you typically use tar to archive the directory first, and then gzip to compress the archive. The tar command has options to do both simultaneously.
Compress a directory:
tar -czvf my_directory.tar.gz my_directory/
-cCreate a new archive.-zCompress the archive withgzip-vVerbose output (show progress).-fSpecify the archive filename.
Decompress a directory:
tar -xzvf my_directory.tar.gz
-xExtract files from an archive.-zDecompress withgzip-vVerbose output.-fSpecify the archive filename.
Using bzip2
bzip2 often provides better compression ratios than gzip but is slower.
Compress a file:
bzip2 my_file.txt
This creates my_file.txt.bz2
Decompress a file:
bunzip2 my_file.txt.bz2
Using xz
xz provides even better compression than bzip2 but is the slowest.
Compress a file:
xz my_file.txt
This creates my_file.txt.xz
Decompress a file:
unxz my_file.txt.xz
Choose a format supported by the downstream tools and balance CPU time against storage savings. Do not assume xz is accepted by a bioinformatics workflow simply because it compresses a file; confirm the tool's input contract. Preserve original sequencing data according to project policy.
Knowledge Check & Assessment
1. Concept Verification
Which Slurm directives control resources, output logging, job naming, and the executable command?
2. Practical Execution
Save the smoke-test script above as smoke-test.sbatch in a suitable working directory. Replace the placeholder partition before submitting. This command captures the actual numeric ID; --parsable can include an optional cluster suffix, which the parameter expansion removes:
SUBMISSION=$(sbatch --parsable smoke-test.sbatch) || exit 1
JOB_ID=${SUBMISSION%%;*}
printf 'Submitted job ID: %s\n' "$JOB_ID"
squeue -j "$JOB_ID"
Check the final state and log
A returned ID means submission was accepted, not that the job has started or finished. Use squeue while it is pending or running. Once it leaves the queue, inspect the accounting record (it can take time to appear) and the job log:
sacct -j "$JOB_ID" --format=JobID,State,ExitCode
cat "hpc-smoke-${JOB_ID}.out"
For this exercise, a successful result is a final batch state of COMPLETED and exit code 0:0, with exactly two output lines: a hostname, then a date (their values and date formatting vary). A PENDING record is waiting, not a failure; a missing log while pending or before the job starts is not by itself a diagnosis. A submission rejection means no accepted job ID was returned: check the partition, any required account, and request limits in local guidance. If the final state is FAILED or the exit code is nonzero, inspect the state, exit code, log contents, and log path; for this command pair, a missing hostname/date line points to a command or script failure. Do not infer completion from an ID or repeatedly resubmit without resolving the reported cause.
3. Troubleshooting
If a job is pending, cancelled, or out of memory, which Slurm fields and site documentation should you inspect first?
Validation boundary: local shell-syntax and mocked-command checks exercised the smoke, array and parallel-step examples, including a failed parallel step. No job was submitted to a real Slurm cluster, and no site's scheduler configuration or policy was validated. Confirm local requirements before submitting your own first job.
References and further reading
Use these official resources to check current software behaviour, terminology, and production guidance. Tool versions and defaults change, so verify commands against the documentation before applying them to a research dataset.