Long-Read Sequencing
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
Learning Objectives & Prerequisites
- Prerequisites: Complete Biological Data Formats, reference-genome concepts, and basic command-line analysis; understand read length and per-read error profiles.
- Objective: Compare PacBio and Nanopore long-read data, choose appropriate QC/alignment/variant or isoform tools, and report platform-specific limitations.
- Expected Output: A documented long-read analysis plan with platform, basecalling or CCS assumptions, reference version, QC metrics, and validation approach.
Suggested route: use the Bioinformatics Learning Path to review any prerequisite stage before continuing.
Long-Read Sequencing Data Analysis
Introduction
Traditional short-read sequencing (Illumina) produces reads that are 150-300 base pairs long. While highly accurate, short reads struggle to resolve complex genomic regions (like repetitive elements) or identify full-length RNA splice isoforms.
Long-read sequencing technologies, pioneered by Oxford Nanopore Technologies (ONT) and Pacific Biosciences (PacBio), generate reads that are 10,000 to over 100,000 base pairs long. This allows researchers to sequence entire mRNA molecules from end to end without fragmentation.
1. Quality Control for Long Reads
Long-read data has a different error profile than short-read data. While PacBio HiFi reads are highly accurate (~99.9%), traditional ONT reads have higher indel (insertion/deletion) error rates.
The standard tool for long-read QC is NanoPlot.
# Install NanoPlot
mamba install -c bioconda nanoplot

# Generate quality control reports for a FASTQ file
NanoPlot -t 8 --fastq long_reads.fastq.gz -o nanoplot_results/
NanoPlot generates beautiful interactive HTML plots showing read length distribution versus read quality (Q-score).
2. Genome Assembly with Long Reads
Because long reads can span across repetitive regions, they produce vastly superior genome assemblies compared to short reads. Flye is the standard assembler for long reads.
# Install Flye
mamba install -c bioconda flye

# Assemble a bacterial genome using Nanopore reads
flye --nano-raw long_reads.fastq.gz --out-dir flye_assembly --threads 16
Once assembled, it is highly recommended to "polish" the genome using tools like Medaka (for Nanopore) or Racon, which corrects the remaining indel errors in the consensus sequence.
3. Transcriptomics: Full-Length Isoform Discovery
One of the most powerful applications of long reads is identifying alternative splicing events. Since a single long read captures the entire transcript, you do not need to statistically infer isoforms - you simply read them directly.
Mapping Long RNA Reads
Minimap2 is the undisputed champion for aligning long reads. It is specifically designed to handle the high error rate and long insertions/deletions characteristic of long-read RNA-seq.
# Map long RNA reads to a reference genome (splice-aware mapping)
minimap2 -ax splice -t 16 hg38.fasta rna_long_reads.fastq.gz > aligned.sam
Isoform Quantification
Once mapped, tools like IsoQuant or FLAMES are used to group the reads into distinct isoforms and quantify their expression.
# Example IsoQuant workflow
isoquant.py --reference hg38.fasta \
            --genedb hg38_annotation.gtf \
            --bam aligned_sorted.bam \
            --data_type nanopore \
            --out_dir isoquant_results/
IsoQuant outputs a high-confidence set of both known and novel isoforms that were completely invisible to standard Illumina sequencing.
Conclusion
Long-read sequencing is rapidly becoming the standard for genome assembly, structural variant detection, and full-length transcriptomics. By mastering tools like NanoPlot, Flye, and Minimap2, you can unlock biological insights that were previously hidden by the limitations of short-read technology.
What Long Reads Reveal That Short Reads Cannot
Illumina short-read sequencing produces highly accurate reads of 150 to 300 base pairs. For most routine applications, including differential expression analysis, variant calling in coding regions, and standard metagenomic profiling, this is sufficient. However, certain biological questions are structurally impossible to answer with short reads, and these are precisely the questions where long-read platforms become essential.
The most significant limitation of short reads is their inability to resolve repetitive sequences and structural variants. The human genome contains roughly 50 percent repetitive sequence, including transposable elements, centromeric repeats, and segmental duplications. When a 150 bp read falls entirely within a repetitive region, it maps to multiple locations with equal probability, and the mapper either discards it or assigns it arbitrarily. Long reads of 10 to 50 kilobases span repetitive regions and anchor to unique flanking sequence on both ends, resolving the mapping problem entirely.
PacBio HiFi vs Oxford Nanopore: The Trade-off in 2026
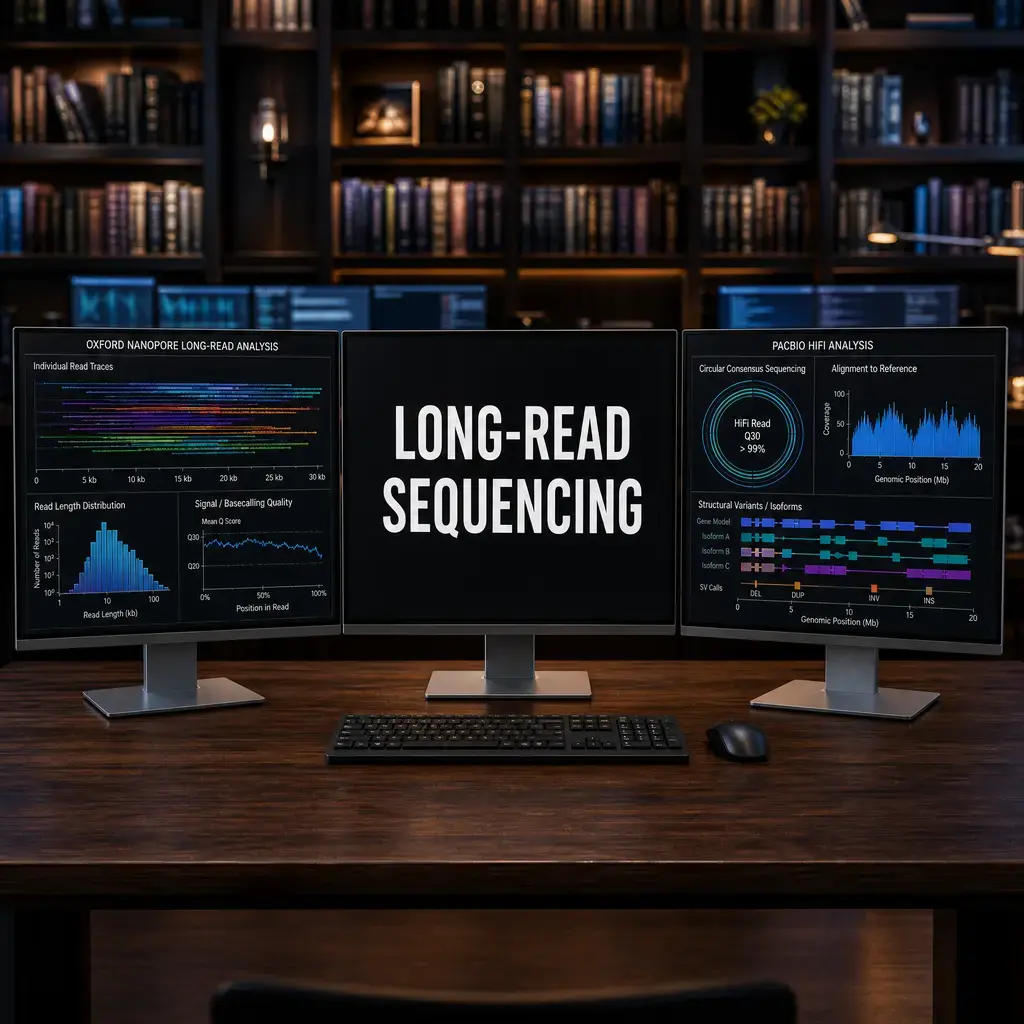
PacBio's HiFi reads, generated using circular consensus sequencing, achieve Illumina-level accuracy (Q30 or higher, meaning fewer than 1 error per 1,000 bases) at read lengths of 10 to 25 kilobases. They are the gold standard for applications where both read length and accuracy are required, such as diploid genome assembly, full-length isoform sequencing, and structural variant discovery with high confidence.
Oxford Nanopore sequencing produces reads that are longer on average (N50 of 20 to 100 kilobases depending on library preparation) but historically had higher raw error rates around 5 to 15 percent per read. Recent chemistry versions and the R10 pore have brought single-read accuracy to Q20 to Q25, which is sufficient for many applications when reads are present in sufficient depth. Nanopore's key advantages are real-time sequencing, the ability to detect base modifications (methylation, for example) directly from the electrical signal, and portability through the MinION device. PacBio's key advantages are higher per-read accuracy and better established computational tools for genome assembly.
Full-Length Transcript Sequencing: Resolving Isoform Complexity
Alternative splicing affects the majority of multi-exon human genes. Short-read RNA-seq can detect which exons are present in a sample, but when a transcript has 10 exons and any 3 of them can be skipped independently, the number of possible isoforms is combinatorially large. Short reads cannot determine which combinations of exon skipping events co-occur in the same transcript molecule.
Long-read isoform sequencing, using PacBio Iso-Seq or Nanopore direct RNA-seq, sequences full-length transcripts from the poly-A tail to the 5-prime cap. Each read represents a single transcript molecule, making it straightforward to determine exactly which combination of exons was present in that molecule. Tools like FLAMES and IsoSeq3 cluster and error-correct the resulting reads to produce a high-confidence isoform catalogue. This approach has revealed thousands of novel isoforms in human tissues that were completely invisible to short-read RNA-seq.
Practical Considerations Before Committing to a Long-Read Experiment
Long-read sequencing costs considerably more per base than short-read sequencing, and the sample preparation requirements are more stringent. DNA and RNA must be of high molecular weight, as fragmented nucleic acids produce short reads that undermine the key advantage of the platform. Extraction protocols designed for short-read sequencing typically involve vortexing or bead-milling steps that shear DNA to a few kilobases; these must be replaced with gentle extraction methods such as plug-based or magnetic-bead protocols.
Before designing a long-read experiment, clearly define what question cannot be answered with short reads. If you are doing standard differential expression analysis or SNP genotyping in well-characterised regions, short reads are less expensive and the tools are more mature. If you are assembling a new genome, resolving structural rearrangements in a cancer sample, or characterising the isoform repertoire of a tissue, long reads are justified and in many cases the only viable approach.
Knowledge Check & Assessment
1. Concept Verification
How do long reads change the trade-off between read length, per-read error, structural context, and sequencing depth compared with short reads?
2. Practical Execution
Inspect a long-read QC or alignment summary and report read-length distribution, mapping rate, reference build, and one platform-specific caveat. Pass Criteria: Record the command or analysis choice, keep the output, and explain why it answers the stated task.
3. Troubleshooting
If mapping or variant results differ strongly from short-read evidence, how will you inspect basecalling, read quality, repeats, coverage, reference choice, and caller assumptions?
Reviewed: September 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: Long-Read Sequencing