Single-Cell Integration: Harmony, RPCA & CCA
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
Learning Objectives & Prerequisites
- Prerequisites: Complete scRNA-seq Basics and understand batches, normalization, PCA, and biological covariates.
- Objective: Compare Harmony, RPCA, and CCA integration approaches and evaluate whether technical variation is reduced without erasing biology.
- Expected Output: An integration comparison with pre/post diagnostics, preserved biological labels, and a documented method choice.
Suggested route: use the Bioinformatics Learning Path to review any prerequisite stage before continuing.
Single-Cell Integration Strategies
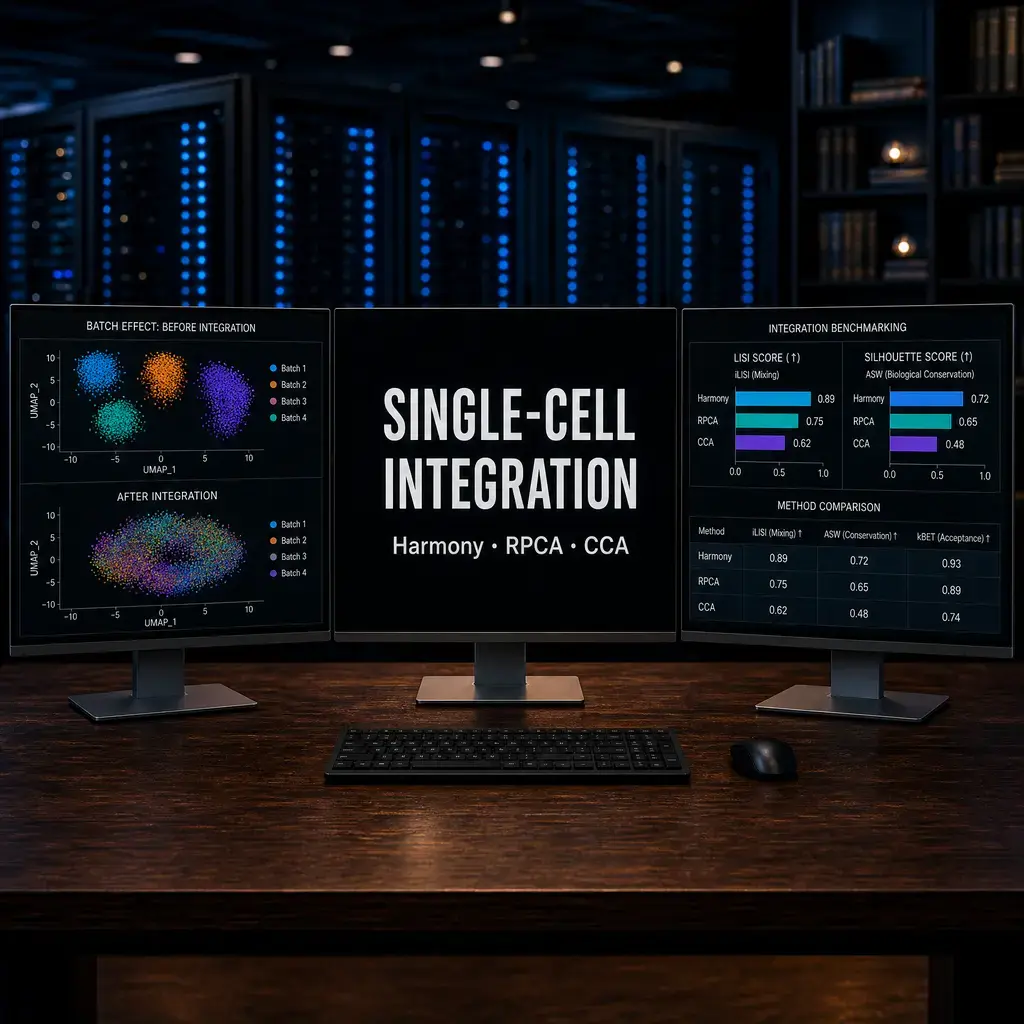
The Batch Effect Problem
When combining single-cell data from multiple patients, different sequencing runs, or different technologies (e.g., 10x Genomics vs. Drop-seq), massive technical variations occur. These are known as batch effects.
If you do not integrate your data, cells will cluster by patient or batch rather than by true biology. Here we cover the three most robust integration strategies.
1. Canonical Correlation Analysis (CCA)
CCA is the classic Seurat v3 integration method. It identifies shared biological states across datasets by finding linear combinations of features that have maximal correlation.
Pros: Extremely powerful. If your datasets are very different (e.g., integrating human and mouse data), CCA forces them to align. Cons: It can over-integrate, meaning it might erase genuine biological differences between patients, creating false hybrid cell types.
library(Seurat)

# Assuming 'obj_list' is a list of normalized Seurat objects
features <- SelectIntegrationFeatures(object.list = obj_list)
anchors <- FindIntegrationAnchors(object.list = obj_list, anchor.features = features, reduction = "cca")
integrated_seurat <- IntegrateData(anchorset = anchors)
2. Reciprocal PCA (RPCA)
RPCA was introduced in Seurat v4 to solve the computational and over-integration issues of CCA. Instead of calculating correlation across all features, it runs Principal Component Analysis (PCA) on each dataset individually, and then projects the PCA of one dataset onto the other.
Pros: Much faster than CCA. It is far more conservative, meaning it preserves true biological variance (e.g., patient-specific disease states) rather than forcing everything to overlap perfectly. Cons: May not fully integrate highly divergent datasets.
# Run PCA on each object first
obj_list <- lapply(X = obj_list, FUN = function(x) {
    x <- ScaleData(x, features = features, verbose = FALSE)
    x <- RunPCA(x, features = features, verbose = FALSE)
})

# Find anchors using RPCA
anchors <- FindIntegrationAnchors(object.list = obj_list, anchor.features = features, reduction = "rpca")
integrated_seurat <- IntegrateData(anchorset = anchors)
3. Harmony (Recommended for Large Cohorts)
Harmony is an algorithm that projects cells into a shared PCA space and iteratively adjusts the coordinates to remove batch-specific technical variation while preserving biological variation.
Pros: Lightning-fast, scales to millions of cells effortlessly, and allows you to integrate across multiple variables simultaneously (e.g., integrating by patient_id AND sequencing_run). You can also fine-tune the strictness using the theta parameter.
Cons: Requires the harmony package instead of native Seurat functions.
import scanpy as sc
import scanpy.external as sce

# Assuming adata is already normalized and PCA has been calculated
# Run Harmony integration using the 'patient_id' batch column
sce.pp.harmony_integrate(adata, 'patient_id')

# Run UMAP on the newly integrated harmony space
sc.pp.neighbors(adata, use_rep='X_pca_harmony')
sc.tl.umap(adata)
library(harmony)

# Merge all objects without native Seurat integration
merged_seurat <- merge(obj_list[[1]], y = obj_list[2:length(obj_list)])
merged_seurat <- NormalizeData(merged_seurat) %>% FindVariableFeatures() %>% ScaleData() %>% RunPCA()

# Run Harmony, specifying the metadata column causing the batch effect
# The 'theta' parameter controls the diversity penalty (higher = stronger integration)
integrated_seurat <- RunHarmony(merged_seurat, group.by.vars = "patient_id", theta = 2)

# Run UMAP on the Harmony reduction rather than standard PCA
integrated_seurat <- RunUMAP(integrated_seurat, reduction = "harmony", dims = 1:30)
Conclusion
- Use Harmony for large cohorts or when integrating across multiple nested batch variables.
- Use RPCA when you have massive datasets and want to conservatively preserve disease-state biological variance.
- Use CCA when integrating highly distinct datasets (like cross-species or different tissues) where you must force alignment to find shared biology.
Knowledge Check & Assessment
1. Concept Verification
Why can an integration that visually mixes batches still be scientifically inappropriate?
2. Practical Execution
Run or inspect two integration diagnostics and justify which method best balances batch mixing with biological separation. Pass Criteria: Record the command or analysis choice, keep the output, and explain why it answers the stated task.
3. Troubleshooting
If integration merges known distinct cell states, how will you reassess covariates, reference choice, dimensions, and whether integration is needed at all?
Reviewed: August 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: Single-Cell RNA-seq