Bulk RNA-seq cell-type deconvolution with MuSiC
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
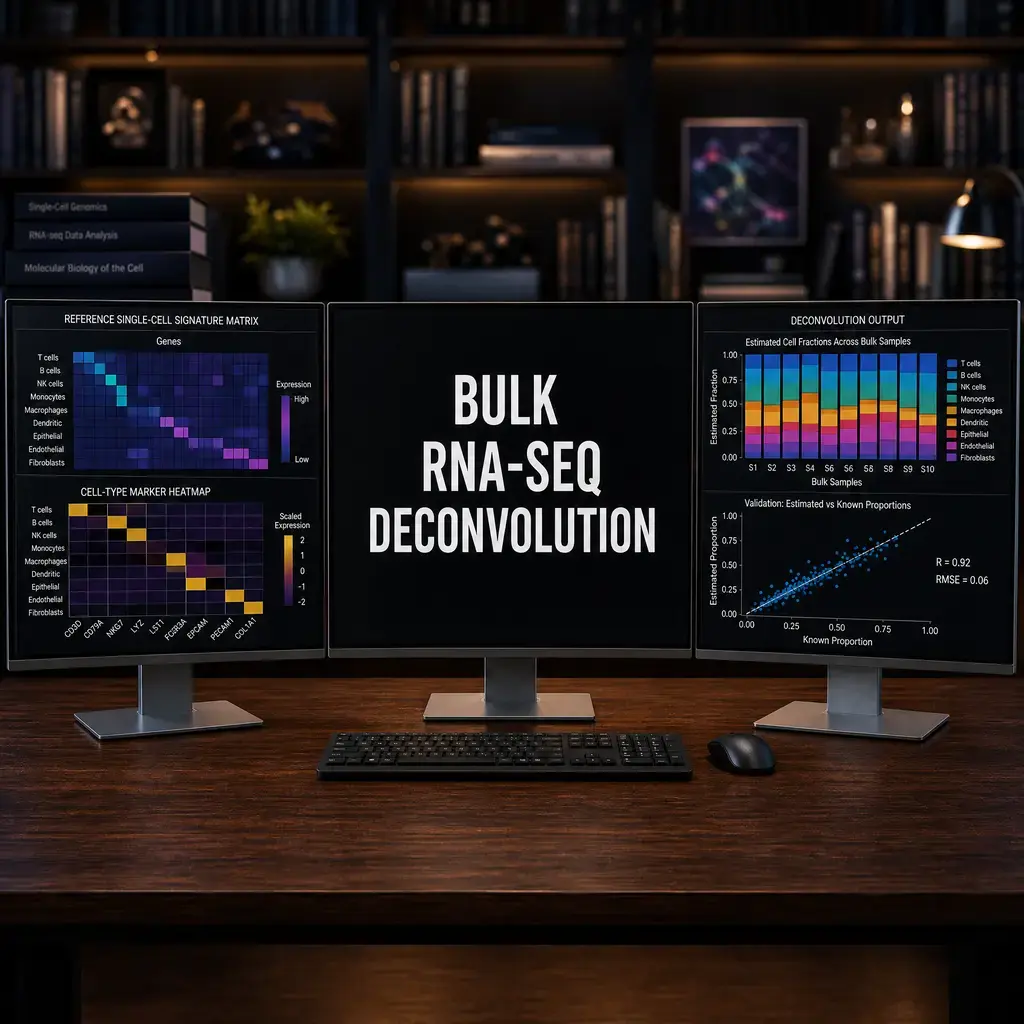
Bulk RNA-seq combines RNA from many cells, so a change in a gene's abundance can reflect a change in cell mixture, expression within cells, or both. This walkthrough uses MuSiC to estimate composition from an annotated single-cell reference, then shows what must be checked before interpreting those estimates.
Format: Conceptual guide. For analysts with prepared bulk counts and an annotated single-cell reference, this guide walks through input review, a MuSiC fit scaffold, and interpretation checks. No data are supplied; readers must prepare both objects and their metadata.
Scope and inputs
MuSiC is a reference-based method designed to use cross-subject single-cell data. You need bulk gene-expression measurements and a single-cell reference with gene counts, cell-type labels, and donor/sample IDs. The code below is an analysis scaffold: replace the named objects and metadata fields with your data, and verify package versions and preprocessing before running it.
What the estimate means
A bulk profile is modeled as a mixture of reference cell-type profiles. The estimated fractions depend on the cell types and expression states represented in that reference. If a relevant population is absent, or if reference and bulk samples differ substantially in condition, tissue, platform, or processing, the model may assign its signal to the closest represented populations. A precise decimal does not remove this ambiguity.
MuSiC's weighting uses cross-subject variation in the single-cell reference. The method estimates proportions; it does not establish that a cell population caused a clinical outcome. Associations with outcomes require a separate, appropriately designed analysis.
Check the reference before fitting
- Confirm cell-type annotations and donor identifiers are present for every reference cell. MuSiC uses the cell-type field as
clustersand donor/sample field assamples. - Check that bulk and single-cell features use the same gene identifier system. Inspect duplicated and missing row names, then quantify shared features in both directions; investigate unexpectedly low overlap before fitting rather than relying on a universal cutoff.
- Review whether the reference covers the tissue, condition, and cell states in the bulk cohort. Record omitted or rare populations rather than treating the listed types as exhaustive truth.
- Use raw read counts for both bulk and single-cell expression, as specified in the MuSiC vignette; do not pass log-transformed values merely because they are convenient for visualization. Check the installed package guidance before adapting preprocessing.
Run MuSiC with your prepared objects
The code assumes that bulk_counts is a genes-by-bulk-samples matrix and sc_reference is a prepared SingleCellExperiment. Both objects are supplied by you; this page does not download or fabricate biological data. MuSiC's official vignette documents installation via devtools::install_github("xuranw/MuSiC") and describes raw read-count inputs. In a fresh R session, first check R.version.string, then install/load the package and required class; record packageVersion("MuSiC"), packageVersion("SingleCellExperiment"), and BiocManager::version() with the run rather than assuming an untested version combination. If installation or class loading fails, stop and resolve that environment issue before fitting. For prepared-object context, follow the vignette's data-preparation example; this page does not construct these objects from files.
library(MuSiC)
library(SingleCellExperiment)

# Replace these names with your prepared objects and metadata fields.
stopifnot(is.matrix(bulk_counts),
          !is.null(rownames(bulk_counts)),
          !is.null(colnames(bulk_counts)),
          inherits(sc_reference, "SingleCellExperiment"))
stopifnot(all(c("cell_type", "donor_id") %in% colnames(colData(sc_reference))))

# Keep shared genes in the same order in both inputs.
shared_genes <- intersect(rownames(bulk_counts), rownames(sc_reference))
if (length(shared_genes) == 0L) {
  stop("No shared gene identifiers; check naming and species.")
}
if (anyDuplicated(rownames(bulk_counts)) || anyDuplicated(rownames(sc_reference))) {
  stop("Duplicate feature identifiers found; resolve them before fitting.")
}
if (anyNA(rownames(bulk_counts)) || anyNA(rownames(sc_reference)) ||
    any(!nzchar(rownames(bulk_counts))) || any(!nzchar(rownames(sc_reference)))) {
  stop("Missing or empty feature identifiers found; resolve them before fitting.")
}
message("Shared genes: ", length(shared_genes), " / ", nrow(bulk_counts),
        " bulk features; ", length(shared_genes), " / ", nrow(sc_reference),
        " reference features.")
if (length(shared_genes) < 2L) stop("Too few shared genes to fit; investigate identifiers and inputs.")
bulk_use <- bulk_counts[shared_genes, , drop = FALSE]
sc_use <- sc_reference[shared_genes, ]

music_results <- music_prop(
  bulk.mtx = bulk_use,
  sc.sce = sc_use,
  clusters = "cell_type",
  samples = "donor_id"
)

# Weighted estimates: rows are bulk samples; columns are cell types.
prop_estimates <- music_results$Est.prop.weighted
stopifnot(is.data.frame(prop_estimates) || is.matrix(prop_estimates))
dim(prop_estimates)
head(prop_estimates)
The identifier columns cell_type and donor_id are examples, not required names; change them to columns actually present in colData(sc_reference). MuSiC uses genes shared between the bulk matrix and reference when markers are left at their default. The output list also contains an all-gene NNLS estimate, gene weights, fit summaries, and variance estimates in the documented implementation. Check the installed version's documentation if an output name differs.
Inspect, plot, and interpret
First inspect dimensions, sample names, cell-type columns, missing values, and whether estimates are finite. MuSiC documents estimates normalized across the included cell types. That sum is conditional on the cell types included in the fit; it does not prove that the reference contains every cell population in the tissue.
# Basic output checks; investigate failures rather than silently dropping values.
stopifnot(nrow(prop_estimates) == ncol(bulk_use))
stopifnot(all(is.finite(as.matrix(prop_estimates))))
range(as.matrix(prop_estimates), na.rm = TRUE)
rowSums(as.matrix(prop_estimates))

# Optional plot. Reshape with base R to avoid an extra plotting dependency.
plot_df <- as.data.frame(as.table(as.matrix(prop_estimates)))
names(plot_df) <- c("bulk_sample", "cell_type", "proportion")
# Plotting code can use ggplot2 after inspecting the values and labels.
Do not treat a stacked bar chart as validation. Compare estimates with an independent measurement from the same samples when available, such as flow cytometry for matching cell populations, and examine agreement across the range rather than relying on one correlation number. Differences in cell definitions, units, sampling, and measurement error affect that comparison. When no independent measurement exists, report that limitation and use checks such as fit diagnostics, reference coverage, stability to defensible reference choices, and known sample annotations as diagnostics, not proof of accuracy.
Hypothetical decision check
Imagine a hypothetical fit that reports proportions summing to one across the cell types included in the reference, while a population of interest is not represented there. Does the sum show that the reported fractions are validated tissue proportions?
Reasoned feedback
No. The estimates are conditional on the included reference types, and normalization to one does not show that the reference is exhaustive or that the fit is accurate. An omitted population can make the reported mixture ambiguous. Review reference coverage and fit diagnostics, test stability under defensible reference choices, and compare with an independent measurement from the same samples when available.
Analysis record to keep
For each run, record the reference tissue and condition, cell-type and donor fields, preprocessing and expression scale, number of shared genes, included cell types, MuSiC version, output dimensions, fit/variance diagnostics, and any external validation. A useful deliverable is this record alongside the sample-by-cell-type estimate table and a plot clearly labeled as an estimate.
References and further reading
- MuSiC package vignette for object preparation, method details, and example outputs.
music_propreference for the current function arguments and output.- Single-cell best practices: bulk deconvolution for broader method assumptions, preprocessing, and reference limitations.