Pseudobulk Differential Expression for scRNA-seq
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
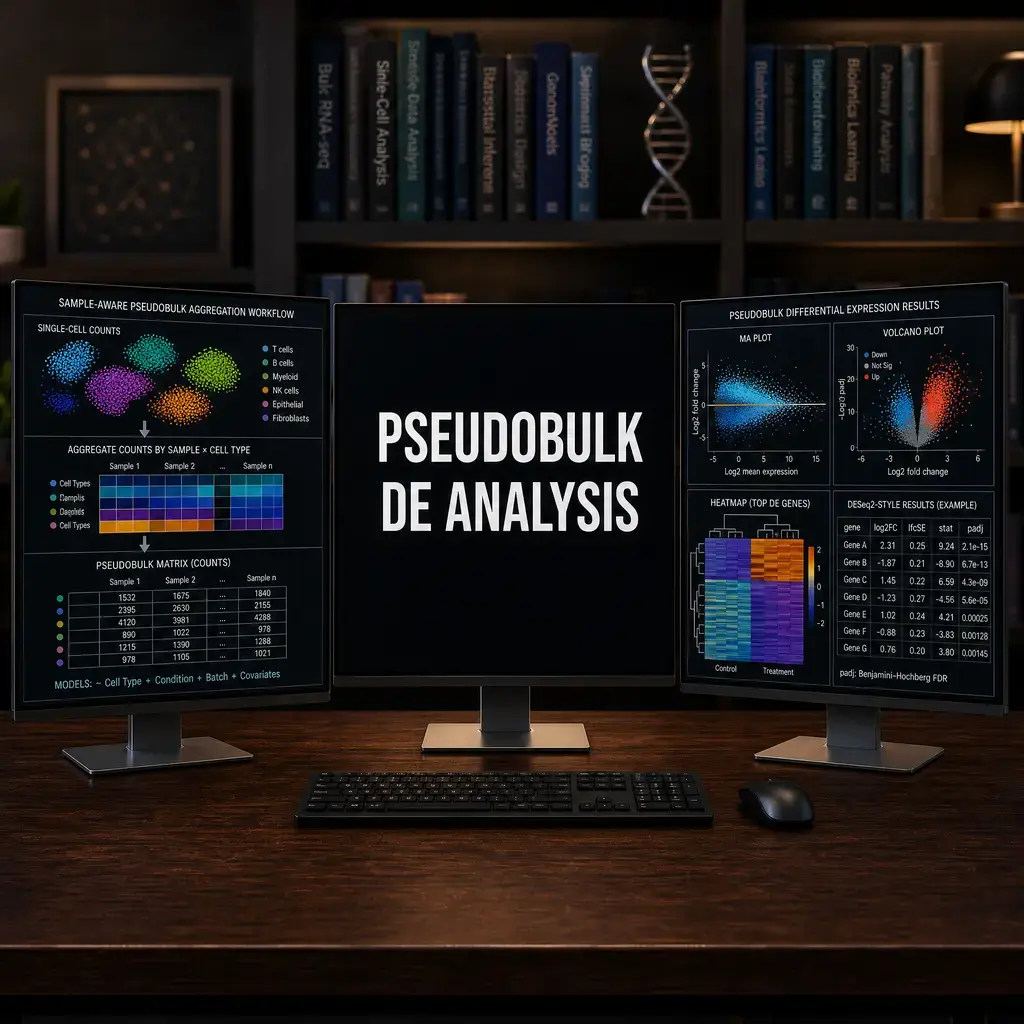
Differential expression in single-cell data needs biological samples, not individual cells, as the independent replicates. This lab shows how to sum raw counts within one annotated cell type and one biological sample, fit a DESeq2 model, and inspect its estimates without treating a plot or p-value as proof of mechanism.
Format: Advanced template. For readers with an annotated Seurat object and an R/Bioconductor environment, this lesson guides sample-level pseudobulk aggregation and DESeq2 interpretation; readers supply and validate their own data rather than downloading a prepared object.
Bring: a processed Seurat object with an RNA assay containing raw counts and per-cell metadata for a cell type, a unique biological sample identifier, and condition. The path /data/seurat_objects/pbmc_processed.rds below is a placeholder, not a downloadable fixture, and the later Healthy-versus-CTCL labels are illustrative; use labels actually present in your experiment. Before proceeding, confirm metadata has one row per cell, the required columns sample_id, condition, and cell_type, and each independent sample maps to one condition. These identifiers must describe the experiment correctly; this example does not perform QC, normalization, annotation, or experimental-design repair. Example versions recorded with the original lesson: R 4.3.2, Seurat 5.0.1, and DESeq2 1.42.0. Seurat argument details can differ across releases.
Why aggregate by biological sample?
Cells from one patient, animal, or specimen share biological and technical sources of variation. Counting thousands of cells as thousands of independent replicates understates between-sample variation and can inflate false discoveries. Pseudobulk sums raw gene counts across cells belonging to the same sample and cell type; the resulting sample profiles can then be analyzed with bulk RNA-seq methods. It does not make samples independent if the study design says otherwise, nor does it correct confounding or replace adequate biological replication.
Define the sample-level input contract
Use one stable sample_id per independent biological sample, not a cell barcode, sequencing lane, or arbitrary group label. Each sample must map to exactly one condition in this simple unpaired example. If the same subject contributes multiple conditions or time points, preserve the subject identifier and use an appropriate paired/repeated-measures design rather than this simple ~ condition model. The subset below uses the metadata column directly, not active Seurat identities.
Replace the example field names and cell-type label with those in your object. Output directories are created beneath the current working directory; use paths you control. Start R in the project directory where you want outputs, set the object path to a real local RDS file, then run the code blocks in order. Check versions in that same R session with R.version.string, packageVersion("Seurat"), and packageVersion("DESeq2"); record them with the analysis rather than assuming the example versions match your installation.
Tested software check: the template completed on Ubuntu with R 4.3.3, Seurat 5.0.1 and DESeq2 1.42.1, using 5,294 public CD4 T cells from Kang et al., GSE96583. The check selected eight genuine donors, four per condition, with only one condition retained per donor; path and contrast labels were changed to the actual control/IFN inputs. Count sums, original sample IDs, sample-sheet alignment, DE outputs and all three white-background figures passed. The original experiment is paired: this deliberately disjoint subset checks the unpaired software route, not the full study. Do not discard matched samples merely to fit this formula. No CTCL conclusion, biological validation or other-platform pseudobulk execution is claimed.
Aggregate raw counts within the chosen cell type
library(Seurat)
library(DESeq2)
library(ggplot2)
library(dplyr)
library(tibble)
library(readr)

seurat_obj <- readRDS("/data/seurat_objects/pbmc_processed.rds")
if (!inherits(seurat_obj, "Seurat")) stop("Input RDS must contain a Seurat object")
if (!"RNA" %in% SeuratObject::Assays(seurat_obj)) stop("Input object must contain an RNA assay")
meta <- seurat_obj[[]]
required <- c("sample_id", "condition", "cell_type")
if (!all(required %in% colnames(meta))) {
  stop("Metadata must contain: ", paste(required, collapse = ", "))
}
if (!identical(rownames(meta), colnames(seurat_obj))) {
  stop("Cell metadata row names must match object cell names")
}

cell_type_of_interest <- "CD4 T"
keep_cells <- rownames(meta)[!is.na(meta$cell_type) &
                              meta$cell_type == cell_type_of_interest]
if (!length(keep_cells)) stop("No cells match the requested cell type")
obj_ct <- subset(seurat_obj, cells = keep_cells)

# Exclude cells missing design labels, then re-check sample-to-condition mapping.
meta_ct <- obj_ct[[]]
valid <- !is.na(meta_ct$sample_id) & !is.na(meta_ct$condition)
obj_ct <- subset(obj_ct, cells = rownames(meta_ct)[valid])
meta_ct <- obj_ct[[]]
if (!nrow(meta_ct)) stop("No cells remain with sample and condition labels")
condition_per_sample <- tapply(as.character(meta_ct$condition),
                                as.character(meta_ct$sample_id),
                                function(x) length(unique(x)))
if (any(condition_per_sample != 1L)) {
  stop("Each sample_id must map to exactly one condition in this example")
}

# Temporary codes prevent Seurat from rewriting underscores or numeric IDs.
# They preserve the same biological samples; they are not new replicates.
sample_ids <- unique(as.character(meta_ct$sample_id))
if (any(!nzchar(trimws(sample_ids)))) stop("sample_id must contain non-empty biological sample IDs")
aggregation_codes <- paste0("sample", seq_along(sample_ids))
obj_ct$pseudobulk_group <- aggregation_codes[match(as.character(meta_ct$sample_id), sample_ids)]

# Seurat sums raw counts within each biological sample.
pb <- AggregateExpression(
  obj_ct, assays = "RNA", group.by = "pseudobulk_group", return.seurat = FALSE
)$RNA
if (!setequal(colnames(pb), aggregation_codes)) {
  stop("Aggregated columns do not match the expected temporary sample codes")
}
# Restore the original IDs before aligning the sample sheet or writing counts.
colnames(pb) <- sample_ids[match(colnames(pb), aggregation_codes)]
# Make the column order explicit and align sample metadata to it.
coldata <- meta_ct[!duplicated(meta_ct$sample_id), c("sample_id", "condition"), drop = FALSE]
coldata <- coldata[match(colnames(pb), as.character(coldata$sample_id)), , drop = FALSE]
stopifnot(identical(as.character(coldata$sample_id), colnames(pb)))
rownames(coldata) <- coldata$sample_id
coldata$condition <- factor(coldata$condition)
if (nlevels(coldata$condition) != 2L) stop("This contrast example expects exactly two conditions")

# Save integer summed counts and the aligned sample sheet for auditability.
dir.create("output/pseudobulk", recursive = TRUE, showWarnings = FALSE)
write_csv(as.data.frame(pb) %>% rownames_to_column("gene"),
          "output/pseudobulk/cd4_counts.csv")
write_csv(coldata %>% rownames_to_column("sample"),
          "output/pseudobulk/sample_metadata.csv")
Check before modeling: each count-matrix column must be one biological sample, and its condition in coldata must be the matching sample-level label. Confirm the assay really contains raw counts. If the conditions are confounded with batch or another covariate, the condition effect cannot be separated from it by adding a formula term alone.
Seurat can rewrite grouping labels containing underscores or beginning with numbers. The temporary codes above avoid changing or merging those original sample IDs; the code restores the real IDs before sample-metadata alignment. Never use renamed groups as an excuse to split one donor into artificial replicates.
Smoke-test the saved files
After running the aggregation block, this checks the documented output files for a gene column, non-negative integer counts, and sample columns aligned to the sample sheet. It does not fit a model or report differential-expression results.
counts_file <- readr::read_csv(
  "output/pseudobulk/cd4_counts.csv",
  show_col_types = FALSE
)
samples_file <- readr::read_csv(
  "output/pseudobulk/sample_metadata.csv",
  col_types = readr::cols(
    sample_id = readr::col_character(),
    .default = readr::col_guess()
  ),
  show_col_types = FALSE
)

stopifnot(
  "gene" %in% names(counts_file),
  all(c("sample", "sample_id", "condition") %in% names(samples_file))
)

count_samples <- names(counts_file)[names(counts_file) != "gene"]
stopifnot(identical(count_samples, samples_file$sample_id))

count_values <- as.matrix(counts_file[count_samples])
stopifnot(
  all(is.finite(count_values)),
  all(count_values >= 0),
  all(abs(count_values - round(count_values)) < 1e-8)
)
If a check fails, inspect the saved files and sample order before modeling. Passing checks establish file structure only; they do not verify the source assay, study design, or biological validity.
Fit DESeq2 and make the contrast explicit
The code below is for two independent conditions and unpaired samples. It uses a simple count prefilter as an example (not a universal cutoff) and leaves DESeq2's result filtering in place. Choose design terms from the study design before looking at outcomes. Do not put both condition and a perfectly confounded batch term into a model and expect it to identify their separate effects.
# Illustrative low-count prefilter; review for your cohort and design.
keep_gene <- rowSums(pb) >= 10
if (!any(keep_gene)) stop("No genes pass the illustrative count filter")
counts_for_de <- pb[keep_gene, , drop = FALSE]
if (any(!is.finite(counts_for_de)) || any(counts_for_de < 0) ||
    any(abs(counts_for_de - round(counts_for_de)) > 1e-8)) {
  stop("DESeq2 input must be finite, non-negative integer raw counts; do not use normalized data")
}

# Replace this design if samples are paired or covariates are needed.
dds <- DESeqDataSetFromMatrix(
  countData = counts_for_de,
  colData = coldata,
  design = ~ condition
)
dds$condition <- relevel(dds$condition, ref = "Healthy")
dds <- DESeq(dds)

# Positive log2 fold change means CTCL relative to Healthy.
res <- results(dds, contrast = c("condition", "CTCL", "Healthy"), alpha = 0.05)
res_ordered <- res[order(res$padj, na.last = TRUE), ]
dir.create("output/deseq2", recursive = TRUE, showWarnings = FALSE)
write.csv(as.data.frame(res_ordered), "output/deseq2/cd4_DE_results.csv")
Before running, confirm the labels are exactly Healthy and CTCL; edit both the reference and contrast for your data. results() reports the specified comparison; padj may be NA for genes filtered by DESeq2 or flagged for outliers. A p-value threshold is not a biological-effect threshold, and significance does not establish causality.
Successful structural check: output/pseudobulk/cd4_counts.csv has a gene column plus one column per retained sample, and sample_metadata.csv has one row per same sample with its condition. The DE results file has gene-level estimates; the plot files are written under output/plots/. Check that the count-column names and metadata sample IDs match exactly and that there is more than one independent sample per modeled condition. These checks establish file alignment and execution, not biological validity or a required direction/significance of effects. Stop if the sample mapping, count assay, or group labels fail; return to metadata and assay provenance rather than interpreting output.
Inspect sample variation and effect estimates
Use the variance-stabilized values to visualize sample relationships, not for DE testing. This PCA helps reveal dominant structure and possible outliers; separation by condition is not guaranteed or required, and overlap does not by itself invalidate the analysis.
vsd <- vst(dds, blind = TRUE)
pca_plot <- plotPCA(vsd, intgroup = "condition") +
  ggtitle("Pseudobulk samples: variance-stabilized counts")
dir.create("output/plots", recursive = TRUE, showWarnings = FALSE)
ggsave("output/plots/pca.png", pca_plot, width = 6, height = 4, bg = "white")

png("output/plots/ma.png", width = 800, height = 600)
plotMA(res, main = "CTCL vs Healthy")
dev.off()

res_df <- as.data.frame(res) %>% rownames_to_column("gene") %>%
  mutate(neg_log10_p = -log10(pmax(pvalue, .Machine$double.xmin)),
         called = !is.na(padj) & padj < 0.05)
volcano <- ggplot(res_df, aes(log2FoldChange, neg_log10_p, color = called)) +
  geom_point(alpha = 0.6) +
  labs(title = "CTCL vs Healthy", x = "Log2 fold change", y = "-log10(p-value)") +
  theme_minimal()
ggsave("output/plots/volcano.png", volcano, width = 6, height = 4, bg = "white")
Read the PCA alongside sample metadata and study design: a batch pattern is a prompt to investigate, not proof that a specific correction is appropriate. VST does not remove batch effects. In the volcano plot, the color marks the adjusted-p-value rule used above; it does not encode a validated effect-size cutoff.
Interpret the result without overclaiming
baseMeanis the mean of normalized counts across samples; low expression can make fold-change estimates less stable.log2FoldChangeis the estimated change for the named contrast. Here, positive values indicate higher estimated expression in CTCL than Healthy.pvalueis the test p-value andpadjis adjusted for multiple testing. Interpret estimates, uncertainty, design and adjusted values together, not one threshold alone.- Pseudobulk tests differences in summed expression for the chosen cell type at the sample level. It does not test changes in cell-type abundance, explain mechanism, or establish clinical utility.
Troubleshoot common problems
- Many unexpectedly tiny adjusted p-values: check that columns are biological samples, not cell barcodes; confirm raw counts were summed; inspect sample labels, condition balance, covariates, and the design.
- Batch dominates PCA: inspect whether batch and condition are confounded. A covariate can be modeled only when the design supports estimating its effect; visualization adjustments do not repair an unidentifiable biological comparison.
- Contrast or model fails: verify condition spelling and factor levels, confirm there are enough independent samples to estimate the specified model, and check that the design matrix is full rank. More cells from the same samples do not replace biological replicates.
- Fold-change direction seems reversed: check the order in
contrast. Forc("condition", "CTCL", "Healthy"), the estimated log2 ratio is CTCL relative to Healthy. - Some adjusted p-values are missing: inspect the DESeq2 result metadata and diagnostics; independent filtering and outlier handling can yield missing values. Do not silently treat them as nonsignificant measurements.
Limits and next checks
Few independent samples limit power and make variance estimates uncertain; there is no universal replicate count that guarantees valid inference. Cell-type misannotation, unequal cell capture, and changing cell composition can affect the interpretation of within-cell-type pseudobulk. Record sample exclusions, annotation rules, count assay, condition labels, design formula, software versions, and filtering choices. For a biological conclusion, validate candidates in an independent cohort or with a suitable orthogonal assay. Analyze cell-type composition separately when that is part of the question.
For paired or repeated-measures studies, adapt the design to the sample structure (for example, include a subject term where estimable); do not reuse the unpaired formula blindly. If condition is perfectly confounded with batch, no model term can disentangle them from these data.
References
- Seurat AggregateExpression reference: grouping and summed-count return contract.
- Seurat differential-expression vignette: sample-level pseudobulk rationale and workflow.
- DESeq2 vignette: count input, designs, contrasts, and diagnostics.
- Squair et al. (2021), “Confronting false discoveries in single-cell differential expression”: evidence on replicate-aware analysis.
- edgeR Bioconductor page: an alternative count-based differential-expression package.
Before analysis, record the versions actually used in your R session with R.version.string, packageVersion("Seurat"), and packageVersion("DESeq2"); the example versions above are not a substitute for your environment record. Re-check package-specific behavior against the official documentation. If a command does not work or you find an error, please report it through the Contact page.
Author: Nasir Mahmood Abbasi, PhD - Category: Single-Cell RNA-seq