Computer and Data Fundamentals for Biologists
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
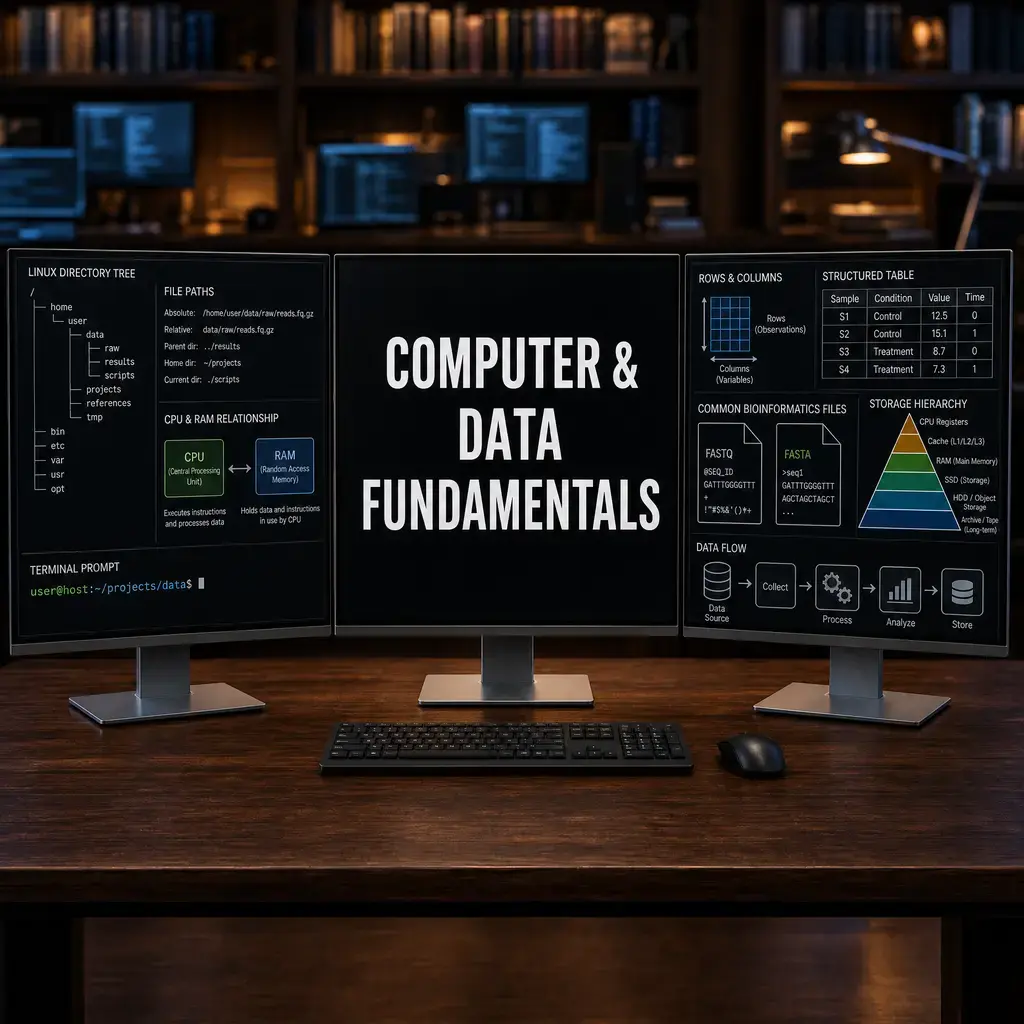
Before running an omics workflow, know where its files live, what resources it can exhaust, and how to check that a transfer arrived intact. This walkthrough builds a project directory and practices safe inspection of compressed FASTQ files.
Format: Hands-on lab. For beginning command-line users: create a small synthetic paired-FASTQ fixture, organize it, and inspect its integrity and resource context. No biological inputs are supplied or required; real datasets need provider-issued checksums.
What you will produce and what you need
By the end, you will have a documented project layout and a verification log for provider-supplied files. You will also be able to tell whether a failure points to storage, memory, permissions, or file integrity.
- Explain the difference between CPU (central processing unit), RAM (random access memory), storage (disk), and network bandwidth and why a bioinformatics workflow can be limited by any of them.
- Describe files, directories, absolute and relative paths, file extensions, basic metadata, and UNIX file permissions.
- Estimate why raw sequencing data often requires large disk and temporary space, and how memory needs grow with certain operations.
- Create a reproducible project folder layout that separates raw data, intermediate files, code, results, and logs, and perform one verified file integrity check (checksum).
Prerequisites:
- A computer with a terminal (macOS Terminal, a Linux shell, or Windows Subsystem for Linux). Commands below use Bash syntax, including brace expansion and
set -o pipefail; use Bash on Linux, macOS, or Windows Subsystem for Linux. - Internet access for downloading example files (optional) and for following references.
- No prior programming experience is required; the lesson focuses on concepts and safe command usage.
Why these fundamentals matter for biological data
Omics work in DNA/RNA sequencing, mass spectrometry proteomics, and large-scale imaging produces many files, often large and compressed. A typical short-read sequencing run can generate tens to hundreds of gigabytes of compressed FASTQ files. A single analysis step (for example, read alignment or large-table joins) can require temporary disk space and memory far in excess of the stored file size, because tools often decompress data or build in-memory indexes.
Understanding where data lives (storage), where it is processed (RAM), who performs the work (CPU), and how data moves between sites (network bandwidth) helps you:
- Choose an appropriate computer or high-performance computing (HPC) queue.
- Organize data so analyses are reproducible and raw data are preserved.
- Diagnose common error messages such as “out of memory”, “disk quota exceeded”, or “permission denied”.
Practical, reproducible workflow
The lab uses a tiny synthetic fixture so every command can be run without downloading biological data. Begin in Bash on Linux, macOS, or WSL; check that bash, gzip, and either GNU sha256sum or shasum are available (command -v bash gzip sha256sum shasum). Do not use synthetic checksums to validate real provider files.
From any working directory, create the two compressed FASTQ files and a clearly local demonstration manifest. The sequences and identifiers below are invented teaching data.
mkdir -p ~/projects/my-study/data/raw
cd ~/projects/my-study/data/raw
printf '@demo/1\nACGT\n+\nIIII\n@demo/2\nTGCA\n+\nIIII\n' | gzip -c > sample_R1.fastq.gz
printf '@demo/1\nTGCA\n+\nIIII\n@demo/2\nACGT\n+\nIIII\n' | gzip -c > sample_R2.fastq.gz
sha256sum sample_R1.fastq.gz sample_R2.fastq.gz > SHA256SUMS
On macOS without sha256sum, make the matching manifest with shasum -a 256 sample_R1.fastq.gz sample_R2.fastq.gz > SHA256SUMS. This locally generated manifest is only a demonstration of checksum mechanics; for downloaded data obtain the manifest from the same provider record as the files and retain it unchanged.
Build the project directory
# From your home or a working directory, create a project folder and subfolders.
mkdir -p ~/projects/my-study/{data/raw,data/processed,scripts,results,logs}
# Create an initial README to document purpose and provenance.
printf "# my-study\n\nRaw data: data/raw/\nProcessed data: data/processed/\n" > ~/projects/my-study/README.md
The command creates separate locations for raw inputs, processed files, scripts, results, and logs. The README records the intended layout. Replace my-study with a project name that is meaningful to you.
Check paths and available storage
- A directory tree at ~/projects/my-study with separate places for raw and processed data, scripts, results, and logs.
- A simple README documenting intentions and locations.
Run these checks from the project directory. Confirm pwd shows the project you intend to inspect before continuing.
# Show where you are and list contents with human-readable sizes.
cd ~/projects/my-study
pwd
ls -lah

# Show disk usage for this project directory (summary).
du -sh . | tee logs/disk_usage_$(date +%F).txt

# Show overall filesystem space and usage.
df -h .
du with free space from df. A large input can need additional scratch space for temporary and intermediate files, so the compressed size alone is not a capacity estimate.Inspect CPU, memory, storage, and transfer constraints
On Linux or WSL, run these read-only checks before a computational job; macOS users can use sysctl -n hw.logicalcpu for logical CPUs and vm_stat for a memory snapshot, while interpreting platform-specific units carefully.
# Linux/WSL: visible logical CPUs and current memory/swap summary
nproc
free -h
# Storage available at this project's location
cd ~/projects/my-study
df -h .
For example, nproc reporting 8 means eight logical CPUs are visible to this environment, not necessarily eight exclusively available cores. free -h reports memory and swap; use the available-memory field as a snapshot, since other processes and scheduler limits can change what a job may use. df -h . reports filesystem capacity and free space, not your quota or scratch allocation. Network bandwidth is transfer rate rather than disk capacity: compare the size of an authorized transfer with observed transfer time, and consult the cluster or provider limits; this short exercise does not benchmark the network. If memory is low, storage is nearly full, or a quota is unclear, pause and ask the system administrator or choose an approved resource before running a large workflow.
Inspect compressed FASTQ inputs
- pwd prints your current path: useful to avoid acting in the wrong directory.
- ls -lah lists files, including hidden ones, with permissions and sizes.
- du -sh . reports the total disk space used by the project and helps plan for expected growth.
- df -h shows remaining space on the filesystem; if you are near capacity you may need to choose a different storage location.
Use the example filenames below only after placing your own files in data/raw/. These commands read the files without creating uncompressed copies.
# Show file type and compression container. This is safe and non-destructive.
file data/raw/sample_R1.fastq.gz
file data/raw/sample_R2.fastq.gz

# Show the compressed and uncompressed sizes (gzip).
gzip -l data/raw/sample_R1.fastq.gz
gzip -l data/raw/sample_R2.fastq.gz

# Peek at the first few lines of a FASTQ file without writing uncompressed contents to disk.
zcat data/raw/sample_R1.fastq.gz | head -n 8
A typical FASTQ record occupies four lines: read identifier, bases, a + separator, and per-base quality values. Seeing the first record is a format spot-check, not a complete validation; the stream test below reads the whole compressed file.
Verify the downloaded bytes
- file reports whether the file is a gzip-compressed stream or plain text, and sometimes the detected character encoding.
- gzip -l lists the compressed size, uncompressed size (if recorded), and compression ratio. Note that some gzip streams may not record exact uncompressed sizes for concatenated streams.
- zcat (or gzcat on macOS with GNU gzip) streams uncompressed text to stdout. The FASTQ format is line-oriented: the first four lines correspond to one read record (header, sequence, + line, quality). Seeing correct FASTQ headers and no binary or error output suggests the file is intact for basic parsing.
For the generated teaching fixture, verify its local SHA-256 manifest as shown. For actual downloaded data, use the provider's manifest and the matching algorithm; the file names must match those listed in that manifest. Never generate a replacement expected hash from a file whose transfer you are trying to verify.
(
  cd ~/projects/my-study/data/raw
  set -e -o pipefail
  sha256sum -c SHA256SUMS 2>&1 | tee ../../logs/checksum_validation_$(date +%F).log
  # If a real provider supplies MD5SUMS instead, use this command, not sha256sum:
  # md5sum -c MD5SUMS 2>&1 | tee ../../logs/checksum_validation_$(date +%F).log
  # On macOS use shasum -a 256 -c SHA256SUMS for SHA-256, or md5 -r -c MD5SUMS for MD5.
  # Also verify gzip streams can be read (a non-zero exit stops this block).
  gzip -t sample_R1.fastq.gz sample_R2.fastq.gz
  echo "gzip exit status: 0"
)
sample_R1.fastq.gz: OK and sample_R2.fastq.gz: OK; gzip exit status should be 0. An edited/truncated file, missing manifest filename, or nonzero gzip status is a stop condition: do not proceed as though validation succeeded. A manifest match verifies bytes against that manifest; it does not establish sample identity, biological suitability, consent, or provenance.Self-check: interpret a deliberate checksum failure
Use only the synthetic fixture. A new temporary directory receives a copy and a test checksum file that retains the original expected hash; the altered copy is compared with that hash. A cleanup trap removes only this temporary directory when the block ends. The original data and SHA256SUMS manifest are left unchanged.
(
  set -e
  cd ~/projects/my-study/data/raw
  tmpdir=$(mktemp -d)
  trap 'rm -rf "$tmpdir"' EXIT

  cp sample_R1.fastq.gz "$tmpdir/sample_R1.check-demo.fastq.gz"
  printf 'x' >> "$tmpdir/sample_R1.check-demo.fastq.gz"
  expected=$(awk '$2 == "sample_R1.fastq.gz" {print $1}' SHA256SUMS)
  test -n "$expected"
  printf '%s  sample_R1.check-demo.fastq.gz\n' "$expected" > "$tmpdir/CHECK-DEMO.SHA256SUMS"

  (
    cd "$tmpdir"
    if sha256sum -c CHECK-DEMO.SHA256SUMS; then
      echo "Unexpected match; inspect the demonstration."
    else
      echo "Expected checksum failure: the altered copy differs from the original hash."
    fi
  )
)
Expected diagnostic: the check should report sample_R1.check-demo.fastq.gz: FAILED, then print the expected-failure message; the temporary directory is removed when the block ends. On macOS, replace sha256sum -c with shasum -a 256 -c. Do not apply this exercise to provider data.
Interpret the checks and count records
- sha256sum -c reads the manifest and checks each listed file. For each entry you should see "OK" or "FAILED". Save the output to logs/checksum_validation_YYYY-MM-DD.log for provenance.
- gzip -t tests whether the gzip stream can be decompressed to the end without producing errors. A non-zero exit code or stderr messages indicate a corrupted stream.
- Important: a checksum check confirms the file you downloaded matches the provider's published bytes. It does not guarantee the biological suitability of the data (correct sample, experimental design, or consent and metadata). Always keep the manifest and your log files with the project.
Output inspection and interpretation
Use the output to decide what to investigate next. File checks answer narrow questions; they do not certify the experiment or metadata.
- ls -lah shows file permissions in the left-most column, e.g., -rw-r--r--. The first character indicates type (dash for regular file, d for directory). The next three are owner permissions (read/write/execute), then group, then others. If you cannot read a file, you may see permission denied errors; changing permissions requires caution and appropriate authorization.
- du -sh . returns the total size used by the directory. If this number is much larger than the sum of compressed FASTQ sizes, check for hidden files, intermediate files, or large temporary directories (for example, alignment index files or temporary directories used by tools).
- gzip -l shows if the uncompressed size recorded in the gzip header is plausible. Some tools concatenate gzip streams (multiple gzip members), which can complicate uncompressed-size reporting; in those cases rely on streaming verification with zcat and counting lines if needed (see commands below).
- sha256sum -c manifest reports "OK" for matching files. If you see "FAILED", the file is different from the manifest. Do not edit the manifest to force a match; instead re-download the affected file and re-verify.
- zcat + head lets you confirm the FASTQ header format. A typical Illumina-style header looks like @
: : : : : : : : : . If FASTQ records look truncated or lines are missing, the file may be corrupt.
Example check: count records without writing an uncompressed copy. The checksum block above runs in a subshell, so this relative path remains rooted at ~/projects/my-study.
# Each FASTQ record is 4 lines. Check the gzip stream before counting it.
set -o pipefail
count_fastq_records() {
  local fastq=$1
  if ! gzip -t "$fastq"; then
    printf 'Cannot count records: gzip integrity check failed for %s\n' "$fastq" >&2
    return 1
  fi
  zcat "$fastq" | awk 'END {
    if (NR == 0) {
      print "No lines found; refusing to report a record count" > "/dev/stderr"
      exit 1
    }
    if (NR % 4 != 0) {
      print "Incomplete FASTQ record: line count is not divisible by 4" > "/dev/stderr"
      exit 1
    }
    print NR / 4 " records"
  }'
}
count_fastq_records data/raw/sample_R1.fastq.gz
Expected result for the invented fixture: 2 records. Negative example: the following command must exit nonzero and must not print a record count if that file is missing or contains a corrupt gzip stream.
count_fastq_records data/raw/missing_R1.fastq.gz
Counting reads scans the full compressed file and can take time; the gzip integrity precheck and count each read the compressed file. Dividing the line count by four is only a line-count sanity check, not full FASTQ validation: it does not check sequence/quality lengths, identifiers, whether paired files are synchronized, or biological correctness. Use available quotas and avoid writing expanded copies when possible.
Troubleshooting: common symptoms, likely causes, and fixes
-
Symptom: "Permission denied" when trying to read or write files.
Likely causes: file owner or permission bits prevent your user from reading/writing; trying to write to a read-only mounted filesystem.
Fixes: check ownership with ls -lah, use sudo only if you understand system-wide implications, or copy files to a directory you own (cp /path/to/source ~/projects/my-study/data/raw/). Contact your sysadmin if adjusting permissions is needed on shared systems. -
Symptom: Out-of-memory (OOM) or process killed during large operations.
Likely causes: tool requires more RAM than available (for example, building a large in-memory index or loading many samples at once).
Fixes: reduce parallelism, split work into smaller batches, run on a machine with more RAM, or use tools designed for streaming (low-memory) processing. -
Symptom: Disk quota exceeded or "No space left on device".
Likely causes: insufficient storage for temporary files, large intermediate files, or logs.
Fixes: clean temporary directories, move raw data to a larger volume, compress processed files (when safe), and review workflow temporary directory settings (many tools respect TMPDIR). Consider using an HPC scratch filesystem for temporary I/O-heavy steps. -
Symptom: Checksum mismatch ("FAILED").
Likely causes: interrupted download, transfer corruption, or manifest mismatch (manifest corresponds to a different filename/version).
Fixes: re-download the file from the original provider; verify that the manifest lists the exact filename; if the provider's manifest lists different names, consult the provider's documentation or contact their support. -
Symptom: gzip -t reports an error or zcat fails partway through.
Likely causes: corrupted gzip stream or truncated file.
Fixes: re-download; if using transfer acceleration (e.g., parallel downloads) try a single-stream download; verify network stability.
Limitations, version caveats, and responsible-use notes
- These examples use GNU utilities. macOS ships BSD variants, and
sha256summay be unavailable by default; use the checksum utility and options documented for your system, and confirm they accept the provider manifest. macOS may also usegzcatwhere this lesson useszcat. Consult the relevant system manual pages before adapting commands. - Checksum algorithms: SHA-256 is preferred for collision resistance. Some archives still publish MD5 manifests; MD5 detects most accidental corruption but is cryptographically weaker. Use whatever algorithm the provider supplies and record which one you used.
- Storage considerations: compressed file size on disk is only part of the story. Some tools need temporary space equal to several times the uncompressed input size (for sorting, indexing, or intermediate BAM files). Plan for large tmp/scratch spaces or pipeline parameters that allow streaming to avoid materializing large intermediates.
- Data governance and ethics: verifying file integrity does not verify consent, provenance, or legal permission to use a dataset. Always confirm metadata, consent, and any access restrictions before reusing or publishing analyses derived from public or controlled-access data.
Decide what to fix when a check fails
- Create and document your project directory: README.md, and separate raw/processed/data locations.
- Verify all downloaded files with the provider's manifest using the same checksum algorithm supplied by the provider.
- Keep verification logs (checksum output, gzip -t output) inside your project logs directory for reproducibility.
- Confirm available RAM and disk before running memory- or I/O-intensive steps; adjust pipeline parallelism and temporary directories accordingly.
- Confirm legal and ethical permissions for data use before analysis or sharing results.
References
- GNU coreutils manual (ls, du, df, mkdir, printf)
- gzip documentation (gzip, zcat, gzip -t)
- OpenSSH and secure transfer recommendations (scp, sftp; see provider instructions for secure download)
- NCBI SRA: downloading public runs with the SRA Toolkit
- GNU Coreutils: calculating and checking SHA-2 checksums
Keep the manifest and verification output with the project so another analyst can see which bytes were checked and against which provider record. Before analysis or sharing, confirm dataset permissions and metadata separately.
These examples use Bash and system-provided command-line utilities rather than a pinned software environment. Record your platform and utility versions alongside an analysis by capturing bash --version, gzip --version, and sha256sum --version (or the relevant macOS utility's version/help output); re-check platform-specific options in the official manuals. If a command does not work, please report it through the Contact page.
Author: Nasir Mahmood Abbasi, PhD - Category: Foundations & Prerequisites