Biological Data Formats: A Practical Field Guide
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
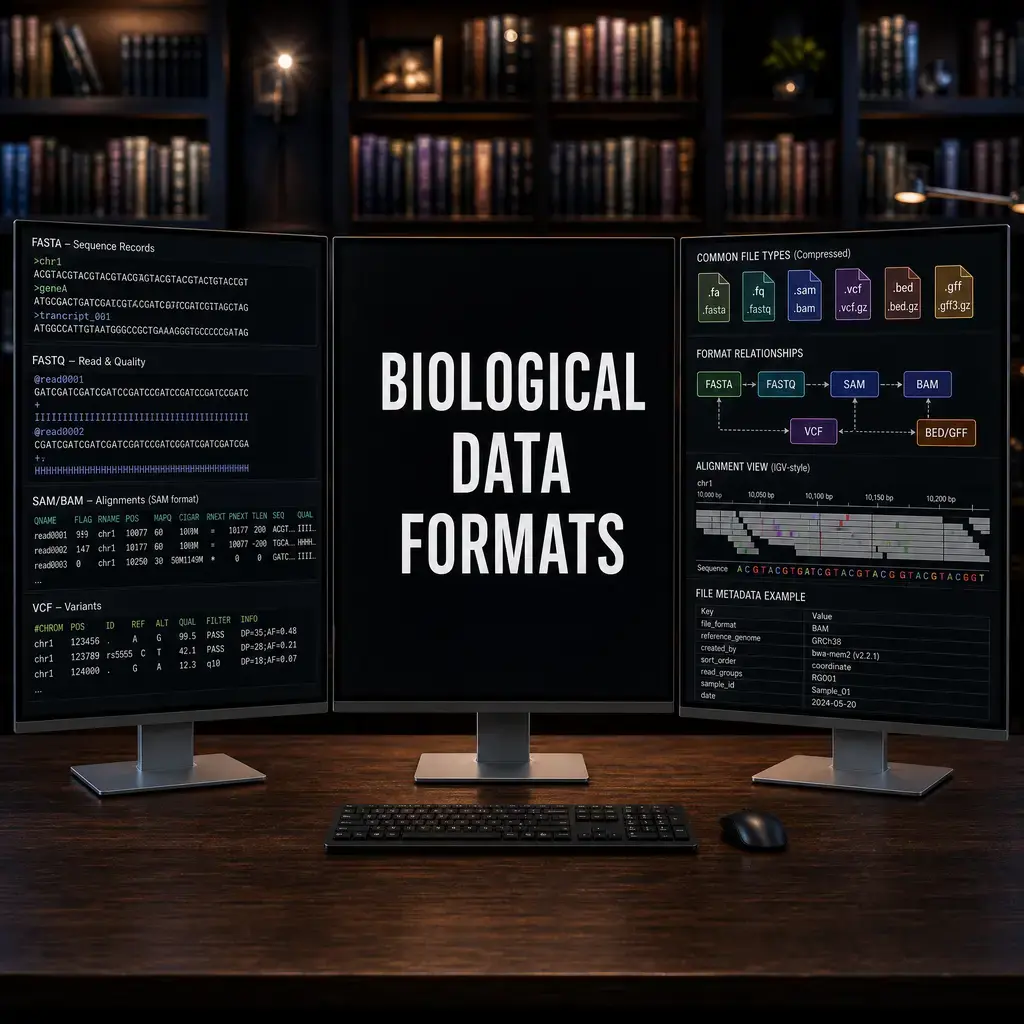
Before a pipeline reads a file, check what it represents, how records are encoded, and which reference or sample metadata it assumes. These inspections can catch format mismatches early; they cannot establish biological validity.
Format: Reference. For learners who can run basic shell commands and have their own sequencing or expression files, this guide demonstrates read-only structural checks and how to interpret their limits; no input dataset is supplied.
Use this guide to identify the common sequencing and expression files, run small read-only checks, and decide what evidence to seek when a check passes or fails. Commands use example filenames and require the listed tools and your own files. The examples are not an end-to-end workflow.
Start with the file's role
| Format | What it represents | Inspect first |
|---|---|---|
| FASTA | Reference or other nucleotide/protein sequences | Are sequence identifiers and lengths from the expected reference? |
| FASTQ | Sequence reads with per-base quality strings | Do records have the expected four-line layout and paired files? |
| SAM/BAM/CRAM | Read alignments, sequence dictionary, and metadata | Does the header name the expected contigs and read groups? |
| VCF/BCF | Variant sites, annotations, and optional sample genotypes | Are reference/build, sample names, and field definitions documented? |
| GTF/GFF | Genome features and their attributes | Do contig names and coordinate conventions match the analysis? |
| Count matrix | Feature-by-sample measurements | Are rows/columns identified, and are values raw counts or transformed? |
Extensions are clues, not proof of format or provenance. A file named .vcf.gz, for example, should be BGZF-compressed for indexed access with the usual tabix/BCFtools tools.
Prepare a safe inspection session
Run these from a directory containing your own inputs, or replace each name with its path. The commands below do not overwrite input files. samtools faidx writes a companion .fai index if one is absent, so choose a writable directory or make that side effect explicit.
# Confirm paths and file sizes, then check detected types
ls -lh reference.fa reads_R1.fastq.gz reads_R2.fastq.gz aligned.bam variants.vcf.gz annotation.gtf counts.tsv
file reference.fa reads_R1.fastq.gz aligned.bam variants.vcf.gz annotation.gtf counts.tsv

# Record tool versions when available
samtools --version | head -n 1
bcftools --version | head -n 1Inspect sequence and read files
FASTA: sequences and reference identity
# Display initial sequence identifiers
 grep -m 6 '^>' reference.fa

# Create a random-access index if absent, then inspect its first entries
samtools faidx reference.fa
head -n 3 reference.fa.fai
The .fai index lists sequence name, length, and byte offsets. Compare sequence names and lengths with the expected assembly, but do not infer the assembly from them alone. Preserve the reference source, release, and checksum. Index creation does not validate that the sequence is the right one for your experiment.
FASTQ: four-line records and paired files
# Count lines and check whether the total is divisible by four
set -o pipefail
zcat reads_R1.fastq.gz | awk 'END {printf "Lines: %d; records if four-line: %d; remainder: %d\n", NR, int(NR/4), NR%4}'

# Inspect three records
zcat reads_R1.fastq.gz | sed -n '1,12p'

# Optional summary, if seqkit is installed
seqkit stats reads_R1.fastq.gz
In the conventional FASTQ layout, each record has a header beginning with @, a sequence, a + separator, and a quality string of matching length. A nonzero line-count remainder is a warning, not a complete parser-level validation. This quick check assumes unwrapped four-line records; malformed wrapping can invalidate that assumption. pipefail makes a decompression failure visible through the pipeline status in common shells such as Bash.
For paired-end data, compare record counts and read-name identifiers in R1 and R2. Equal counts alone do not show that mates are in the same order or correctly paired. The R-first check below reads both gzip-compressed files in lockstep, verifies four-line records and equal sequence/quality lengths, and compares the first header token after removing a terminal /1 or /2. It assumes the remaining token is identical between mates; if your provider uses a different naming convention (for example, mate labels in a second header field), inspect its documentation and adapt the normalization rather than accepting a mismatch blindly.
R: compare paired read identifiers
Save this base R script as check_mates.R and run Rscript --vanilla check_mates.R reads_R1.fastq.gz reads_R2.fastq.gz. It streams one four-line record at a time rather than loading both files into memory.
args <- commandArgs(trailingOnly = TRUE)
if (length(args) != 2L) stop("Usage: Rscript check_mates.R R1.fastq.gz R2.fastq.gz", call. = FALSE)
check_mates <- function(paths) {
  handles <- lapply(paths, gzfile, open = "rt")
  on.exit(lapply(handles, close), add = TRUE)
  next_id <- function(handle, path) {
    block <- readLines(handle, n = 4L, warn = FALSE)
    if (!length(block)) return(NULL)
    if (length(block) != 4L) stop(path, ": incomplete four-line record", call. = FALSE)
    if (!startsWith(block[[1]], "@") || !startsWith(block[[3]], "+") ||
        nchar(block[[2]], type = "bytes") != nchar(block[[4]], type = "bytes")) {
      stop(path, ": malformed record near ", block[[1]], call. = FALSE)
    }
    token <- sub("[[:space:]].*$", "", substring(block[[1]], 2L))
    if (!nzchar(token)) stop(path, ": missing read identifier", call. = FALSE)
    sub("/[12]$", "", token)
  }
  n <- 0L
  repeat {
    a <- next_id(handles[[1]], paths[[1]])
    b <- next_id(handles[[2]], paths[[2]])
    if (is.null(a) && is.null(b)) break
    n <- n + 1L
    if (is.null(a) || is.null(b)) stop("FAIL: different record counts at record ", n, call. = FALSE)
    if (!identical(a, b)) stop("FAIL: mate identifiers/order differ at record ", n, call. = FALSE)
  }
  if (n) cat(sprintf("PASS: %d paired records; normalized identifiers match in order\n", n))
  else cat("PASS: both files are empty\n")
}
check_mates(args)
Python alternative: the same paired-record check
This standard-library route requires Python 3.9 or later for removesuffix. It applies the same first-token and terminal mate-suffix convention to ordinary read names.
python3 - reads_R1.fastq.gz reads_R2.fastq.gz <<'PY'
import gzip, itertools, sys

def records(path):
    with gzip.open(path, "rt") as f:
        while True:
            block = list(itertools.islice(f, 4))
            if not block:
                return
            if len(block) != 4:
                raise ValueError(f"{path}: incomplete four-line record")
            name, seq, plus, qual = (line.rstrip("\r\n") for line in block)
            if not name.startswith("@") or not plus.startswith("+") or len(seq) != len(qual):
                raise ValueError(f"{path}: malformed record near {name!r}")
            yield name[1:].split()[0].removesuffix("/1").removesuffix("/2")

n = 0
for n, (a, b) in enumerate(itertools.zip_longest(records(sys.argv[1]), records(sys.argv[2])), 1):
    if a is None or b is None:
        raise SystemExit(f"FAIL: files have different record counts (first unmatched record {n})")
    if a != b:
        raise SystemExit(f"FAIL: mate identifiers/order differ at record {n}: {a!r} vs {b!r}")
print(f"PASS: {n} paired records; normalized identifiers match in order" if n else "PASS: both files are empty")
PY
A PASS establishes only that the parsed records have matching normalized identifiers in order under the stated convention; it does not establish sample identity or biological validity. Any malformed record, count difference, or identifier mismatch stops the check with the first location to investigate. Both small checks assume readable gzip inputs and ordinary first-token identifiers; adapt the opener for uncompressed FASTQ. They are not full FASTQ specification or compression-integrity validators. Do not treat quality scores as comparable across files until the encoding and instrument/pipeline provenance are known.
Check alignments and variants against their references
SAM/BAM/CRAM: headers and file integrity
# Header metadata, including @SQ sequence dictionary and @RG read groups
samtools view -H aligned.bam | sed -n '1,40p'

# Lightweight truncation check, followed by alignment-flag summaries
samtools quickcheck aligned.bam && echo "quickcheck passed" || echo "quickcheck failed"
samtools flagstat aligned.bam | sed -n '1,10p'
Compare each @SQ sequence name and length with the intended reference, and check that read-group/sample identifiers agree with your sample sheet. quickcheck examines the header and file ending; it does not read the whole alignment body, so it can miss internal corruption. flagstat reads all records and reports flag-based categories. A mapping percentage is a diagnostic to investigate, not a universal pass/fail threshold or proof of alignment quality.
VCF/BCF: definitions, samples, and indexing
# Print metadata header and a small record sample
bcftools view -h variants.vcf.gz | sed -n '1,80p'
bcftools view variants.vcf.gz | sed -n '1,10p'

# Summarize records; index statistics require a usable index
bcftools stats variants.vcf.gz | sed -n '1,40p'
bcftools index --stats variants.vcf.gz
Read the ## metadata and final #CHROM header line. Check sample names, declared INFO/FORMAT fields such as DP or AD, and any reference/build information. Confirm REF alleles against the exact reference used by the calling workflow. A syntactically accepted VCF does not prove a variant is real; provenance, caller-specific filters, and appropriate validation still matter.
bcftools index --stats reads an existing index and reports per-contig record counts; it is not itself an integrity test. If no index is available, create one only when you intend to write a sidecar, for example bcftools index variants.vcf.gz for a BGZF-compressed VCF.
Read annotations and count tables
GTF/GFF: feature columns and coordinates
head -n 20 annotation.gtf
cut -f3 annotation.gtf | sort | uniq -c | sort -nr | sed -n '1,20p'
GTF/GFF feature lines have nine tab-separated fields; column 3 is the feature type and column 9 carries attributes. GTF and GFF3 have distinct attribute conventions, so inspect the file's declared version and use a parser that matches it. Their feature coordinates are generally 1-based and inclusive; convert carefully when passing intervals to software using zero-based, half-open coordinates. Confirm sequence names against the reference. The cut example assumes records are tab-delimited and that comment/directive lines do not need special handling.
Count matrix: dimensions, identifiers, and value scale
# Inspect the header and a few rows
head -n 6 counts.tsv

# Show the first row and number of tab-delimited fields
awk -F '\t' 'NR==1 {print; print "Columns:", NF}' counts.tsv
Establish whether rows are genes, transcripts, or other features, and whether columns map to samples in a separate sample sheet. Find out whether values are raw counts, normalized abundance, or transformed measurements from the quantification method and its documentation. Integer-looking values alone do not establish that a matrix contains raw counts. Methods that model raw counts, including common differential-expression workflows, should not be given normalized or log-transformed values as if they were raw counts.
Use failures to narrow the diagnosis
- FASTQ line remainder or decompression error: test the gzip stream with
gzip -t reads_R1.fastq.gz, verify transfer checksums, and use a FASTQ-aware validator. Recover an intact source where possible; do not silently repair records based only on line counts. - Contigs missing during region extraction: compare BAM
@SQnames and lengths with the FASTA index. Achrprefix difference can be a naming mismatch, while different lengths can signal a different assembly. Resolve provenance before renaming or realigning. - VCF fields rejected or samples absent: inspect the header and sample columns, then compare with the producing caller's documentation and logs. Reconstructing or editing a header without provenance can mislabel data.
- Decimal values in a count table: determine whether the values are normalized or transformed and retrieve raw quantifier output if a count-based method requires it. Do not round normalized measurements to manufacture counts.
What a successful check does not establish
File parsers and summary commands detect selected structural problems. They do not establish that files belong to the same sample, reference build, assay, or experimental design. Keep a sample sheet with explicit sample IDs and file paths; record reference and annotation releases, tool versions, checksums, and the commands used. These checks do not replace statistical QC, assessment of biological replication, or independent validation of findings.