Experimental Design and Batch Effects
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
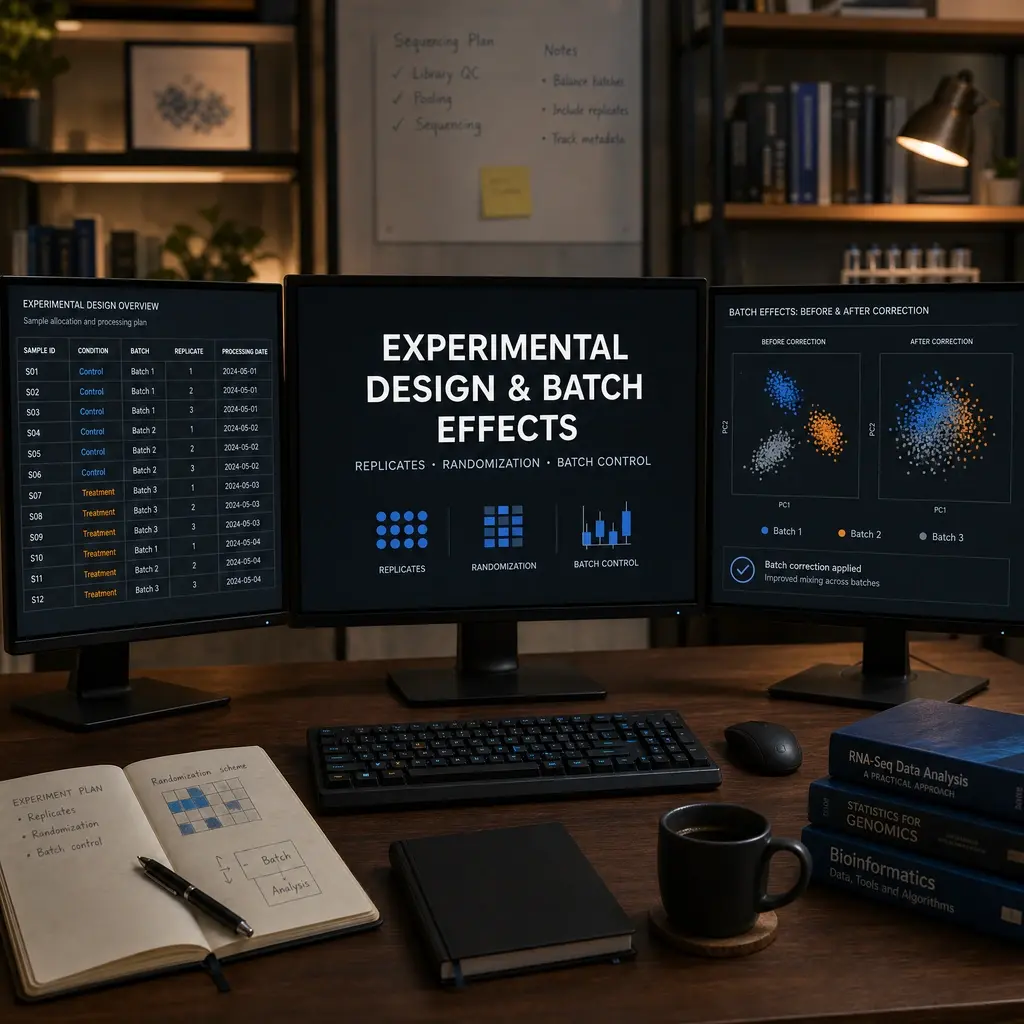
Before sequencing, ask whether the biological comparison can be separated from the way samples are processed. A sample sheet and a condition-by-batch table expose design problems while they can still be fixed. This guide walks through those decisions, then shows lightweight metadata checks and an exploratory expression PCA.
Format: Conceptual guide. For learners planning or reviewing an omics study: you will assess replication, batch balance, and sample-to-metadata alignment, then run an exploratory PCA on a tiny synthetic count table or your own prepared counts; no biological dataset is supplied.
Start with the experimental unit
The experimental unit is the unit independently assigned to a treatment or condition. It is often a participant, animal, culture, or independently prepared sample. Repeated measurements from one unit and technical replicates do not create additional independent biological replicates. Keep the unit identifier in metadata so the analysis can represent pairing or repeated measurements when the design requires it.
A batch is a group processed under shared technical conditions, such as a sequencing run, plate, reagent lot, operator, or processing date. Record the actual factors that could differ; a single column called batch may not capture all relevant sources of variation. Give each row an unambiguous sample ID, and maintain a separate, stable mapping from that ID to raw files.
Check whether condition and batch are separable
Plan for each processing batch to contain samples from each condition whenever practical. Randomize sample order within blocks that matter to the study, such as donor or collection site, and preserve paired samples together when the protocol requires it. Record the allocation method and random seed. Balance is a design goal, not a guarantee that all other covariates are balanced.
| Design | Batch 1 | Batch 2 | What can be learned |
|---|---|---|---|
| Crossed | control and treated | control and treated | Condition and batch effects may be modeled separately, subject to adequate replication and the full design. |
| Perfectly confounded | control only | treated only | The data cannot distinguish condition from batch. A model cannot identify both effects from this design. |
A table with both conditions in every batch is a useful first check, but it does not prove the design is adequate. Replication, missing combinations, paired structure, and other covariates still matter. If condition and batch encode identical information, the model matrix is rank-deficient and the separate coefficients are not identifiable. If that happens before processing, redesign the allocation; after data collection, state the limitation and avoid claiming a correction recovered the separate effects.
Build and validate a sample sheet
Use one row per measured sample. If several samples come from one experimental unit, repeat its unit ID in those rows rather than treating those rows as independent units. Include all variables needed to link data files and describe the planned model. This small invented sample sheet is a code fixture, not a sample-size recommendation or biological result:
sample_id,experimental_unit,condition,batch,library_id,sex,collection_date
S01,Donor01,control,Lane1,L01,F,2024-01-12
S02,Donor02,control,Lane2,L02,M,2024-01-13
S03,Donor03,treated,Lane1,L03,F,2024-01-12
S04,Donor04,treated,Lane2,L04,M,2024-01-13
Use the same metadata file for either language. The Python route requires Python 3 and pandas; the base R route requires only R. Save and run one validator, not both. Each checks required fields, blanks, and unique sample IDs, prints the batch-by-condition counts, and writes metadata.validated.csv. Repeated experimental-unit IDs remain allowed because repeated or paired measurements can be legitimate; this structural check does not validate identities, replication, or model suitability.
cat > metadata.csv <<'EOF'
sample_id,experimental_unit,condition,batch,library_id,sex,collection_date
S01,Donor01,control,Lane1,L01,F,2024-01-12
S02,Donor02,control,Lane2,L02,M,2024-01-13
S03,Donor03,treated,Lane1,L03,F,2024-01-12
S04,Donor04,treated,Lane2,L04,M,2024-01-13
EOF
Base R validator
Save this equivalent base R script as validate_metadata.R. It has no package installation step.
meta <- read.csv("metadata.csv", check.names = FALSE, colClasses = "character",
                na.strings = character(), strip.white = FALSE)
required <- c("sample_id", "experimental_unit", "condition", "batch", "library_id")
missing_columns <- setdiff(required, names(meta))
if (length(missing_columns) > 0) {
  stop(paste("Missing columns:", paste(missing_columns, collapse = ", ")))
}
for (column in required) {
  values <- trimws(meta[[column]])
  if (anyNA(values) || any(values == "")) {
    stop(paste("Missing or blank values in", column))
  }
}
if (anyDuplicated(meta$sample_id)) {
  duplicates <- unique(meta$sample_id[duplicated(meta$sample_id) |
                                        duplicated(meta$sample_id, fromLast = TRUE)])
  stop(paste("Duplicate sample_id values:", paste(duplicates, collapse = ", ")))
}
print(table(meta$batch, meta$condition))
write.csv(meta, "metadata.validated.csv", row.names = FALSE, na = "")
cat("Wrote metadata.validated.csv\n")
Rscript --version
Rscript validate_metadata.R
Python validator
Save as validate_metadata.py. Install pandas only if it is not already available in the Python environment you manage.
python --version
python -m pip install pandas
python validate_metadata.py
import pandas as pd

meta = pd.read_csv("metadata.csv", dtype={"sample_id": "string"})
required = ["sample_id", "experimental_unit", "condition", "batch", "library_id"]
missing_columns = sorted(set(required) - set(meta.columns))
if missing_columns:
    raise ValueError(f"Missing columns: {missing_columns}")

for column in required:
    values = meta[column].astype("string").str.strip()
    if values.isna().any() or values.eq("").any():
        raise ValueError(f"Missing or blank values in {column}")

if meta["sample_id"].duplicated().any():
    duplicates = meta.loc[meta["sample_id"].duplicated(keep=False), "sample_id"].tolist()
    raise ValueError(f"Duplicate sample_id values: {duplicates}")

print(pd.crosstab(meta["batch"], meta["condition"], dropna=False))
meta.to_csv("metadata.validated.csv", index=False)
print("Wrote metadata.validated.csv")
With the fixture, each lane contains one control and one treated sample. If a validator stops for a missing field, blank value, or duplicate sample ID, correct the file rather than bypassing the check. A passing result only verifies these structural conditions.
Explore expression patterns with PCA
PCA can help reveal dominant patterns in an expression matrix, but it is exploratory and cannot label a pattern as biological or technical by itself. Choose either the base R or Python implementation below. Both require a finite, non-negative count matrix in counts.csv, with feature IDs in the first column and sample IDs as column names, plus the validated metadata produced by either validator. Counts columns must match metadata sample IDs exactly; each implementation aligns metadata to the count-column order. The log-CPM-like transform is a simple exploratory transform, not a count-model input for differential-expression testing.
Shared invented count fixture
This tiny table uses the same four invented sample IDs as the metadata above. It tests file structure and code flow only; values do not represent an assay and support no biological conclusion.
cat > counts.csv <<'EOF'
feature_id,S01,S02,S03,S04
gene_A,10,12,40,38
gene_B,30,28,15,17
gene_C,5,8,22,18
gene_D,50,45,55,60
EOF
Base R PCA
Save as pca.R and run with Rscript pca.R. It uses base R only.
counts_df <- read.csv("counts.csv", row.names = 1, check.names = FALSE)
meta <- read.csv("metadata.validated.csv", stringsAsFactors = FALSE,
                 check.names = FALSE)
counts <- as.matrix(counts_df)

if (!is.numeric(counts) || anyNA(counts) || any(!is.finite(counts)) || any(counts < 0)) {
  stop("counts.csv must contain finite, non-negative numeric values")
}
if (anyDuplicated(colnames(counts)) || anyDuplicated(meta$sample_id)) {
  stop("Sample IDs must be unique in counts and metadata")
}
if (!setequal(colnames(counts), meta$sample_id)) {
  stop("Counts columns and metadata sample_id values must match exactly")
}
meta <- meta[match(colnames(counts), meta$sample_id), , drop = FALSE]
if (anyNA(meta$sample_id)) stop("Could not align every count column to metadata")

libsize <- colSums(counts)
if (any(libsize == 0)) stop("A sample has zero total counts")
cpm <- sweep(counts, 2, libsize, "/") * 1e6
logcpm <- log2(cpm + 1)
variable <- apply(logcpm, 1, function(x) length(unique(x)) > 1)
if (sum(variable) < 2) stop("Need at least two variable features for a 2D PCA")
pca <- prcomp(t(logcpm[variable, , drop = FALSE]), center = TRUE, scale. = FALSE)
if (ncol(pca$x) < 2) stop("PCA returned fewer than two components")
pc_df <- data.frame(PC1 = pca$x[, 1], PC2 = pca$x[, 2], meta,
                    check.names = FALSE)
write.csv(pc_df, "pca_coordinates.csv", row.names = FALSE)
print(summary(pca))
Python PCA
Save as pca.py. This route requires Python 3 and NumPy; it uses the same transform, variable-feature filter, sample alignment checks, and output fields as the R example. Install NumPy only if it is not already available.
python --version
python -m pip install numpy
python pca.py
import csv
import numpy as np

with open("counts.csv", newline="", encoding="utf-8") as handle:
    reader = csv.DictReader(handle)
    count_columns = reader.fieldnames
    if not count_columns or count_columns[0] != "feature_id":
        raise ValueError("counts.csv must start with a feature_id column")
    sample_ids = count_columns[1:]
    if not sample_ids or len(sample_ids) != len(set(sample_ids)):
        raise ValueError("Count sample IDs must be present and unique")
    feature_ids = []
    rows = []
    for row in reader:
        feature_ids.append(row["feature_id"])
        try:
            rows.append([float(row[sample_id]) for sample_id in sample_ids])
        except (TypeError, ValueError) as exc:
            raise ValueError("Counts must be numeric for every feature and sample") from exc
counts = np.asarray(rows, dtype=float)
if counts.ndim != 2 or counts.shape[0] == 0 or counts.shape[1] == 0:
    raise ValueError("counts.csv must contain at least one feature and sample")
if not np.isfinite(counts).all() or (counts < 0).any():
    raise ValueError("counts.csv must contain finite, non-negative numeric values")
if len(feature_ids) != len(set(feature_ids)):
    raise ValueError("Feature IDs must be unique")

with open("metadata.validated.csv", newline="", encoding="utf-8") as handle:
    metadata_reader = csv.DictReader(handle)
    metadata_fields = metadata_reader.fieldnames or []
    metadata = list(metadata_reader)
if "sample_id" not in metadata_fields:
    raise ValueError("Metadata must contain sample_id")
metadata_ids = [row["sample_id"] for row in metadata]
if len(metadata_ids) != len(set(metadata_ids)):
    raise ValueError("Sample IDs must be unique in counts and metadata")
if set(sample_ids) != set(metadata_ids):
    raise ValueError("Counts columns and metadata sample_id values must match exactly")
metadata_by_id = {row["sample_id"]: row for row in metadata}
aligned_metadata = [metadata_by_id[sample_id] for sample_id in sample_ids]

library_sizes = counts.sum(axis=0)
if (library_sizes == 0).any():
    raise ValueError("A sample has zero total counts")
logcpm = np.log2(counts / library_sizes * 1e6 + 1)
variable = np.ptp(logcpm, axis=1) > 0
if int(variable.sum()) < 2:
    raise ValueError("Need at least two variable features for a 2D PCA")
samples_by_features = logcpm[variable, :].T
centered = samples_by_features - samples_by_features.mean(axis=0)
u, singular_values, _ = np.linalg.svd(centered, full_matrices=False)
if len(singular_values) < 2:
    raise ValueError("PCA returned fewer than two components")
coordinates = u[:, :2] * singular_values[:2]
with open("pca_coordinates.csv", "w", newline="", encoding="utf-8") as handle:
    fields = ["PC1", "PC2"] + metadata_fields
    writer = csv.DictWriter(handle, fieldnames=fields)
    writer.writeheader()
    for index, sample_metadata in enumerate(aligned_metadata):
        writer.writerow({"PC1": coordinates[index, 0], "PC2": coordinates[index, 1],
                         **sample_metadata})
print("Wrote pca_coordinates.csv")
Run each PCA script in the directory containing counts.csv and metadata.validated.csv. A successful run writes pca_coordinates.csv with four sample rows, PC1, PC2, and the seven metadata fields. PCA axes may be sign-flipped between implementations; compare the represented subspace and sample structure, not the signs alone. Both stop if sample IDs are duplicated, missing, or extra, if counts are invalid or a library has zero total, or if fewer than two features vary. Do not bypass an alignment failure. The PCA does not draw a plot; color points by condition and shape by batch for an exploratory view. With unscaled features, high-variance features can dominate. A successful software run does not validate assay quality, design adequacy, or biological interpretation. The official DESeq2 worked vignette explains count-matrix/sample-metadata correspondence for RNA-seq.
Choose a modeling response
- Conditions represented across batches: include batch and condition in the analysis design when supported by the study structure. For a simple independent-sample RNA-seq comparison, a DESeq2 design might be
~ batch + condition; it is an example, not a universal formula. Paired, repeated-measures, interaction, or nested designs require terms that reflect those units and questions. - Perfect confounding or missing combinations: inspect the model matrix and resolve the design before data collection if possible. When the study is already complete and effects are not identifiable, report that limitation; removing a batch column from a formula makes an assumption, not a recovery of its effect.
- Considering batch-adjusted expression for visualization or another downstream task: use a method appropriate for the data type and purpose, and include the biological variables whose signal must be protected as required by that method. For example, the sva package documents ComBat's model matrix for adjustment variables. Do not treat an adjusted matrix as a replacement for the count model used for differential-expression inference.
A PCA colored by batch may show a strong technical pattern, but it does not prove all condition-associated differences are technical. Clustering by condition does not rule out batch effects either. Compare diagnostics, design structure, and model assumptions; report sensitivity analyses rather than presenting a corrected visualization as proof.
Investigate unexpected patterns before excluding samples
- One sample separates from the rest: check sample identity and raw-data QC, including read quality and mapping or library metrics appropriate to the assay. A rare biological state can also be an outlier. Exclude a sample only with a documented, assay-relevant reason and report the decision.
- A known technical variable tracks principal components: check whether it is recorded consistently and whether it is confounded with condition. Include it in models only if the design permits its effect to be estimated.
- Biological patterns change after adjustment: revisit the input, the adjustment variables, and the method's assumptions. Compare the unadjusted and adjusted analyses for the stated purpose. Large changes are a reason to investigate, not proof that either output is correct.
Limits and records to keep
Batch adjustment can account for measured technical structure under suitable design and method assumptions. It cannot create information that was not collected, and methods can alter biological variation when variables are confounded or the model is misspecified. The appropriate procedure depends on assay, data type, study design, and downstream question.
Keep the sample-to-file mapping, metadata version, processing allocation and random seed, exclusions with reasons, software/package versions, and the model formula with analysis records. When datasets come from different centers, protocols, or platforms, document those differences and interpret harmonized data cautiously.
Worked decision checklist
- Identify the independently assigned experimental unit and count biological replicates at that level.
- Record each measured sample, its unit, condition, batch, file identifier, and relevant covariates.
- Cross-tabulate condition against each planned batch. Investigate empty combinations and exact overlap before processing.
- Randomize within appropriate blocks and save the allocation procedure and seed.
- After data generation, inspect sample identity and assay-specific QC before interpreting PCA.
- Specify a model that represents the design. If condition and batch cannot be separated, describe the limitation instead of claiming correction solved it.
For additional method details, consult the DESeq2 vignette, the Bioconductor sva vignette, and R's prcomp documentation. These examples do not replace method-specific analysis guidance.
Example software versions were not recorded. Before adapting the snippets, capture your environment with python --version, python -c "import pandas; print(pandas.__version__)", and R --version, and record those outputs with your analysis. Re-check commands against the official documentation; report errors or broken steps through the Contact page.
Author: Nasir Mahmood Abbasi, PhD - Category: Foundations & Prerequisites