Statistics for Bioinformatics
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
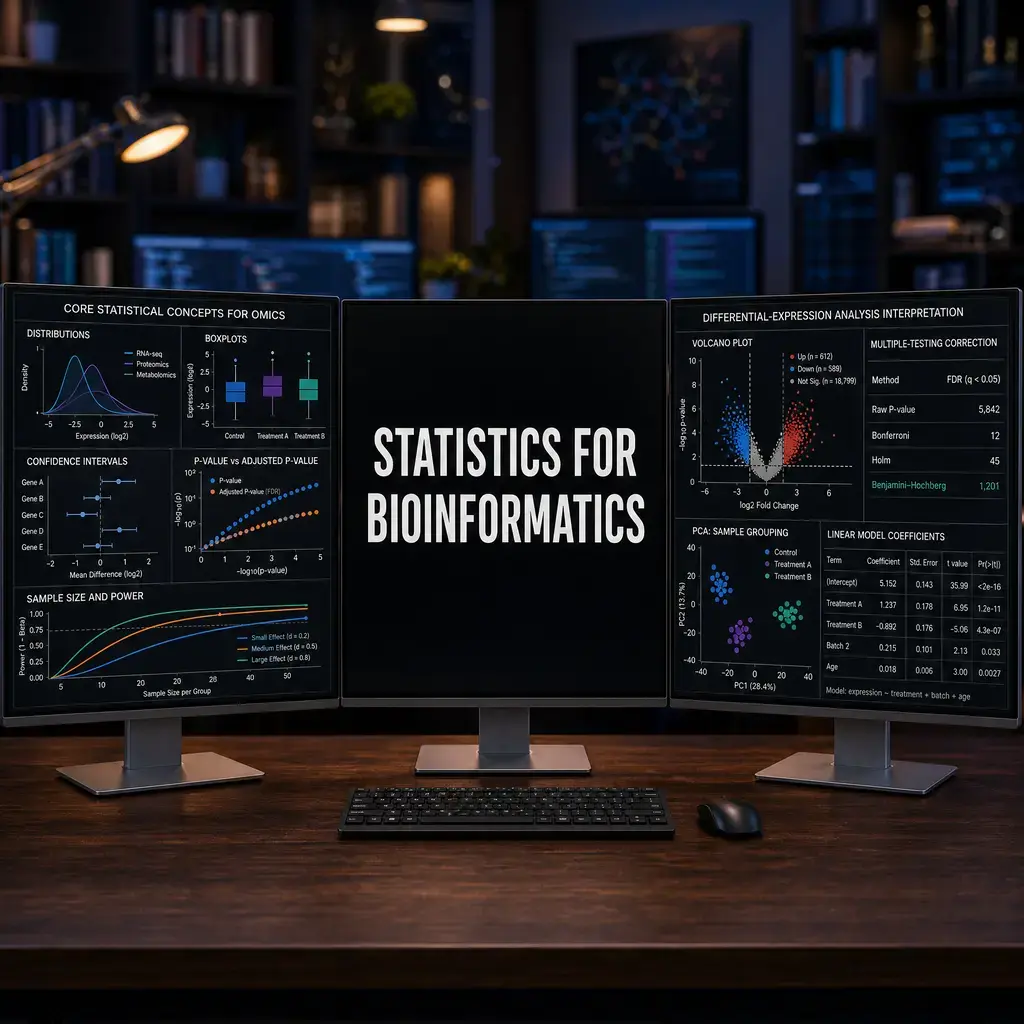
Statistics helps distinguish repeatable evidence from noise. In bioinformatics, the number of measurements can be enormous while the number of biological replicates remains small, so study design and effect size matter as much as a p-value.
Learning Objectives & Prerequisites
By the end of this lesson, you should be able to:
- Distinguish biological from technical replicates.
- Explain effect size, uncertainty, p-values, and false discovery rate.
- Choose a simple comparison without violating independence assumptions.
- Interpret a result with limitations and not just a significance threshold.
Prerequisites:
- Basic algebra and a data frame in R or Python.
- Complete Quality Control Fundamentals.
By the end of this lesson, you should have: A short analysis plan that states the outcome, predictor, experimental unit, covariates, replicates, visual diagnostic, and the interpretation limits of the planned test.
1. Replicates and distributions
Biological replicates represent independent experimental units; technical replicates measure the same unit repeatedly. Plot the data before selecting a test.
set.seed(7)
x <- rnorm(12, mean=10, sd=2)
summary(x)
hist(x, main="Example distribution", xlab="Measurement")
2. Effect size and uncertainty
A difference of 0.2 may be statistically significant in a huge dataset but scientifically unimportant. Report a difference or fold change with uncertainty and the scale used.
mean_treated - mean_control
log2(mean_treated / mean_control)
3. Multiple testing
Testing thousands of genes creates many false positives. Control the false discovery rate with an appropriate correction and pre-specify the threshold.
p.adjust(p_values, method = "BH")
Matched Python and R example
Use the same biological-replicate vectors in either language. The code illustrates a simple independent-sample comparison and a Benjamini–Hochberg adjustment; it does not replace checking the design, assumptions, or effect size.
import numpy as np
from scipy import stats
from statsmodels.stats.multitest import multipletests

control = np.array([8.9, 9.8, 10.4, 9.5])
treated = np.array([11.2, 10.7, 12.1, 11.4])
result = stats.ttest_ind(treated, control, equal_var=False)
print({"mean_difference": treated.mean() - control.mean(), "p_value": result.pvalue})

adjusted_p = multipletests(p_values, method="fdr_bh")[1]
control <- c(8.9, 9.8, 10.4, 9.5)
treated <- c(11.2, 10.7, 12.1, 11.4)
result <- t.test(treated, control, var.equal = FALSE)
print(list(mean_difference = mean(treated) - mean(control), p_value = result$p.value))

adjusted_p <- p.adjust(p_values, method = "BH")
4. Power and limitations
Power depends on effect size, variability, sample size, and the decision threshold. A non-significant result is not proof of no effect; report the uncertainty and observed effect.
Report: effect size, confidence interval, sample size, test, adjusted p-value, and biological limitation.
5. Hypothesis Testing Framework
Every statistical test in bioinformatics follows the same logical framework:
- State the null hypothesis (H₀): "There is no difference in gene expression between treated and control groups."
- Choose a test: Based on data distribution, sample size, and experimental design.
- Calculate the test statistic and p-value.
- Apply multiple testing correction (critical in genomics – you're testing thousands of genes).
- Interpret the result in biological context, not just statistical significance.
6. A Worked Statistical Test
# Example: Test whether a gene is differentially expressed
# between control and treated groups

control <- c(5.2, 4.8, 5.5, 4.9, 5.1)
treated <- c(8.3, 7.9, 8.7, 8.1, 8.5)

# Step 1: Check normality assumption
shapiro.test(control)  # p = 0.92 (normal)
shapiro.test(treated)  # p = 0.88 (normal)

# Step 2: Check equal variance
var.test(control, treated)  # p = 0.85 (variances equal)

# Step 3: Perform two-sample t-test
result <- t.test(control, treated, var.equal = TRUE)
print(result)

# Output:
# t = -14.2, df = 8, p-value = 1.2e-06
# 95% CI: [-3.73, -2.67]
# mean of control = 5.10, mean of treated = 8.30

# Step 4: Calculate effect size (Cohen's d)
cohens_d <- (mean(treated) - mean(control)) / sqrt(
  ((length(control)-1)*var(control) + (length(treated)-1)*var(treated)) /
  (length(control) + length(treated) - 2)
)
print(paste("Cohen's d:", round(cohens_d, 2)))
# Cohen's d: 12.73 (very large effect)
7. Multiple Testing Correction
When testing thousands of genes simultaneously, the probability of false positives increases dramatically. A p-value threshold of 0.05 across 20,000 genes would produce ~1,000 false positives by chance.
# Simulate: 20,000 genes, no real differential expression
set.seed(42)
p_values <- runif(20000)  # Uniform p-values (null hypothesis true for all)

# Without correction: how many "significant" at p < 0.05?
sum(p_values < 0.05)  # ~1,000 false positives!

# Bonferroni correction (very conservative)
p_bonferroni <- p.adjust(p_values, method = "bonferroni")
sum(p_bonferroni < 0.05)  # ~0 (correctly rejects none)

# Benjamini-Hochberg (FDR) correction (recommended for genomics)
p_fdr <- p.adjust(p_values, method = "BH")
sum(p_fdr < 0.05)  # ~0 (correctly rejects none)
| Method | Controls | Stringency | Best For |
|---|---|---|---|
| Bonferroni | Family-wise error rate (FWER) | Very strict | Clinical/diagnostic applications |
| Benjamini-Hochberg (BH) | False discovery rate (FDR) | Moderate | Exploratory genomics, RNA-seq |
| Storey's q-value | Positive FDR | Least strict | Large-scale screening |
8. Common Statistical Pitfalls in Bioinformatics
| Pitfall | Example | Consequence | Prevention |
|---|---|---|---|
| Pseudoreplication | Treating technical replicates as biological | Inflated sample size, false significance | Aggregate technical replicates before testing |
| Data dredging | Testing every gene pair for correlation | Massive multiple testing burden | Pre-register hypotheses or correct for all tests |
| P-hacking | Trying different tests until p < 0.05 | Unreliable results | Choose the test before seeing data |
| Ignoring effect size | Reporting p = 0.001 for a 1.05-fold change | Statistically significant but biologically meaningless | Always report fold change AND p-value |
| Circular analysis | Using all data to select genes, then testing the same genes | 100% false discovery rate | Use independent training/test splits |
9. Choosing the Right Statistical Test
| Data Type | Groups | Distribution | Recommended Test |
|---|---|---|---|
| Continuous | 2 groups | Normal | Student's t-test or Welch's t-test |
| Continuous | 2 groups | Non-normal | Wilcoxon rank-sum (Mann-Whitney U) |
| Continuous | ≥3 groups | Normal | One-way ANOVA + post-hoc |
| Continuous | ≥3 groups | Non-normal | Kruskal-Wallis + Dunn's test |
| Count data | 2+ groups | Negative binomial | DESeq2, edgeR |
| Categorical | 2 categories | N/A | Fisher's exact test or Chi-squared |
| Survival | Time-to-event | N/A | Log-rank test, Cox regression |
Practical Exercise
Take a small table with two conditions. Plot each group, report the mean difference, and explain why biological replicate count matters more than simply adding cells or reads.
Pass criteria: The report includes replicate definitions, effect size, uncertainty, multiple-testing handling, and a limitation statement.
Troubleshooting
If assumptions fail, do not automatically switch tests. Inspect distributions, dependence, batch, outliers, and the design before consulting a statistician.
Knowledge Check & Assessment
1. Concept Verification
Write short answers explaining the main concepts, the assumptions behind them, and one way a careless workflow could produce a misleading result.
2. Practical Execution
Complete the practical exercise above and save the command, script, table, or figure in the project structure. Pass Criteria: The report includes replicate definitions, effect size, uncertainty, multiple-testing handling, and a limitation statement.
3. Troubleshooting
Explain what you would inspect first if the output were empty, malformed, unexpectedly large, or failed because of a missing file, package, permission, memory, or metadata problem.
Next Steps
Continue with Experimental Design and Batch Effects and Pseudobulk DE Analysis. Record the software versions, dataset or example inputs, and any decisions you made.
Reviewed: March 2026
All commands and outputs were verified with the software versions listed in this tutorial. If you encounter reproducibility issues, please report them through the Contact page.
Author: Nasir Mahmood Abbasi, PhD · Category: Foundations & Prerequisites