R and Tidyverse Fundamentals
Nasir Mahmood Abbasi, PhD
Bioinformatics Educator
This short R workflow turns a wide gene-count table into one row per gene and sample, checks that the sample IDs agree with metadata, and summarizes total counts for a basic library-size check. The example is synthetic; its counts demonstrate data handling, not biological evidence.
Format: Hands-on lab. Beginners with basic file and command-line skills will create two small synthetic TSV inputs, run an R script, and inspect its QC table and plot; no biological data are supplied or required.
What you need and what you will make
Use an R session with tidyverse and here installed. The fresh Ubuntu setup and complete synthetic lab were checked on Ubuntu 24.04.4 with R 4.3.3, Tidyverse 2.0.0, dplyr 1.2.1, here 1.0.2, and ggplot2 4.0.3. This is a recorded working combination, not a lockfile or a promise that every package release and operating system works.
The script assumes the project root contains the two tab-separated files below. Each count-table row is a gene, the first column is named gene, and every remaining column is one sample with non-negative integer counts. Metadata has exactly one row per sample and includes sample_id and condition.
# data/raw/gene_counts.tsv
 gene	S01	S02	S03
TP53	150	175	160
BRCA1	320	280	305
MYC	890	920	900

# data/metadata/samples.tsv
sample_id	condition
S01	control
S02	treated
S03	treated
Ubuntu 24.04: install R and system prerequisites first
This Bash block is for Ubuntu 24.04 with administrator access. It installs R, standard build tools, development headers and a basic font before any R package compilation. It changes system packages, not just this project. On a shared server, ask its administrator to provide these prerequisites; do not assume you can use sudo. If R and the packages already load in a managed environment, keep that environment and skip this system-installation step.
sudo apt-get update &&
sudo apt-get install -y --no-install-recommends \
  r-base r-base-dev build-essential pkg-config ca-certificates \
  libcurl4-openssl-dev libssl-dev libxml2-dev libuv1-dev \
  libfontconfig1-dev libfreetype6-dev libharfbuzz-dev libfribidi-dev \
  libpng-dev libtiff-dev libjpeg-dev libwebp-dev libicu-dev zlib1g-dev \
  fonts-dejavu-core
The libraries cover HTTPS and XML imports (curl, openssl, xml2), filesystem support (fs), and plot text and images (systemfonts, textshaping, ragg).
Fontconfig and FreeType find and draw fonts; HarfBuzz and FriBidi support text shaping; PNG, TIFF, JPEG and WebP libraries support image output. The ICU headers allow stringi to use system ICU rather than build its bundled fallback, and DejaVu supplies a basic runtime font on minimal Ubuntu. System requirements can change with package releases; consult the maintainers' system-requirement guidance. These libraries do not replace the R-package installation below.
Use R (including Rscript) and the tidyverse and here packages. Start in a fresh practice directory, not a directory containing research files you need to keep; these commands write the named input files and create the script and output folders. Paste the complete R code in the next section into scripts/01-tidy-qc.R using a text editor.
mkdir -p tidy-qc/data/raw tidy-qc/data/metadata tidy-qc/scripts tidy-qc/results
cd tidy-qc
touch .here
mkdir -p .r-library
cat > data/raw/gene_counts.tsv <<'EOF'
gene	S01	S02	S03
TP53	150	175	160
BRCA1	320	280	305
MYC	890	920	900
EOF
cat > data/metadata/samples.tsv <<'EOF'
sample_id	condition
S01	control
S02	treated
S03	treated
EOF
Rscript --version
Check the package setup before running the lab
The commands below are Bash terminal commands, run from tidy-qc. They put a writable project package library first without replacing system-wide packages. Install dplyr before the other packages so a preinstalled copy does not silently decide the dependency versions. Downloads and source compilation can take time; do not continue past an installation error. If the packages already load in a suitable managed environment, skip installation but run the readiness check there and keep using that environment.
Keep .r-library/ out of Git and create a fresh library when changing R versions or operating systems. Record the loaded versions with the readiness check below; copying installed packages is not an environment lockfile.
R_LIBS_USER="$PWD/.r-library" Rscript --vanilla -e '
lib <- Sys.getenv("R_LIBS_USER")
options(repos = c(CRAN = "https://cloud.r-project.org"),
        timeout = max(600, getOption("timeout")), Ncpus = 2)
install.packages("dplyr", lib = lib)
install.packages(c("tidyverse", "here"), lib = lib)
required <- c("dplyr", "tidyverse", "here")
loaded <- vapply(required, function(pkg) {
  requireNamespace(pkg, lib.loc = lib, quietly = TRUE)
}, logical(1))
if (!all(loaded)) {
  stop("Installation incomplete: ", paste(required[!loaded], collapse = ", "))
}
stopifnot(packageVersion("dplyr", lib.loc = lib) >= "1.1.1")
'
Do not treat exit code 0 from install.packages() alone as success. R package compilation or downloads can fail with warnings while R itself exits successfully. The installation block above checks that the required packages actually load from the project library and stops on an incomplete installation. A ten-minute download timeout and two build workers make the source-install route less fragile; use one worker on a resource-limited machine. A stable network is still required.
Next, start a fresh R process with the same library selection. The join argument relationship requires dplyr 1.1.1 or newer; that is an API minimum, not a guarantee that every newer dependency combination is compatible. Expected evidence is successful package loading, the loaded versions and library paths, not just an installer exit code.
R_LIBS_USER="$PWD/.r-library" Rscript --vanilla -e '
stopifnot(requireNamespace("tidyverse", quietly = TRUE),
          requireNamespace("here", quietly = TRUE))
stopifnot(packageVersion("dplyr") >= "1.1.1")
suppressPackageStartupMessages(library(tidyverse))
suppressPackageStartupMessages(library(here))
for (pkg in c("tidyverse", "dplyr", "here", "ggplot2")) {
  cat(pkg, as.character(packageVersion(pkg)), "\n")
}
print(.libPaths())
sessionInfo()
'
If setup fails: stop before the analysis and find the first failed package in the log. An XML-only remedy was insufficient in the independent minimal-Ubuntu check: curl also needed libcurl headers, openssl needed OpenSSL headers, fs needed libuv, and systemfonts needed Fontconfig and FreeType. The Ubuntu prerequisite block includes these libraries and the downstream text/image build dependencies, rather than repairing packages one at a time.
If the error is a download timeout or unavailable mirror, distinguish it from a missing-header or compiler error. After restoring the network, rerun the same package-installation block and the separate readiness check; do not skip readiness because some packages compiled. If the readiness check fails, the lab is not ready to run. Do not fix source-build failures by deleting another project's package library or changing research inputs.
A second failure involved a newer dbplyr importing filter_out from an older dplyr 1.1.4. Updating dplyr in the dedicated library before reinstalling the failed packages resolved that combination. Restart a previously opened R session after updates, and inspect .libPaths(), find.package("dplyr") and packageVersion("dplyr") if the old copy still loads.
The complete Ubuntu prerequisite route above was checked separately from the earlier repaired-library result; the earlier XML-only remedy was not a complete setup. See the Tidyverse installation guidance, xml2 documentation and R's library-path documentation for system requirements and library selection. R's installation documentation explains parallel builds and dependencies; the download documentation explains timeouts.
Keep this lab inside its own project root
touch .here creates a local root marker before R starts. This matters if tidy-qc is inside another Git project: automatic discovery can otherwise select the ancestor instead. The workflow also declares here::i_am("scripts/01-tidy-qc.R") before any file paths, so an already loaded here session is reset to the script's intended project. Save the complete script at that exact relative path and run from tidy-qc; a wrong location should stop with a root error, not send you looking for inputs in an unrelated directory.
After saving the R code below, run this Bash command from tidy-qc. Repeat the library selection in a new terminal; .here selects file paths, not R packages.
R_LIBS_USER="$PWD/.r-library" Rscript --vanilla scripts/01-tidy-qc.RThe script writes results/sample_qc.tsv and results/reads_qc.png. If you chose an existing managed R environment instead, run Rscript --vanilla scripts/01-tidy-qc.R from its active shell without selecting the project library.
Run the workflow
library(tidyverse)
library(here)
here::i_am("scripts/01-tidy-qc.R")

counts_file <- here("data", "raw", "gene_counts.tsv")
meta_file   <- here("data", "metadata", "samples.tsv")
out_table   <- here("results", "sample_qc.tsv")
out_plot    <- here("results", "reads_qc.png")

counts  <- read_tsv(counts_file, show_col_types = TRUE)
samples <- read_tsv(meta_file, show_col_types = TRUE)

# Check table shape and keys before reshaping or joining.
stopifnot("gene" %in% names(counts), all(c("sample_id", "condition") %in% names(samples)))
stopifnot(!anyNA(counts$gene), !anyDuplicated(counts$gene))
stopifnot(!anyNA(samples$sample_id), !anyDuplicated(samples$sample_id))
count_samples <- setdiff(names(counts), "gene")
stopifnot(length(count_samples) > 0L, !anyDuplicated(count_samples))
stopifnot(setequal(count_samples, samples$sample_id))

# Do not silently treat missing, negative, or non-numeric counts as valid counts.
# In base R, is.numeric() accepts both integer and double vectors.
stopifnot(all(vapply(counts[count_samples], is.numeric, logical(1))))
stopifnot(all(vapply(counts[count_samples], function(x) all(is.finite(x) & x >= 0), logical(1))))
# This lesson's contract is integer-valued counts, not arbitrary non-negative reals.
stopifnot(all(vapply(counts[count_samples], function(x) all(x == floor(x)), logical(1))))

samples <- samples %>%
  mutate(condition = factor(condition, levels = c("control", "treated")))
long_counts <- counts %>%
  pivot_longer(
    cols = all_of(count_samples),
    names_to = "sample_id",
    values_to = "raw_count"
  )

# Each gene-sample row should match one metadata row; unexpected row multiplication
# would indicate duplicate sample IDs in the metadata (checked above).
joined <- long_counts %>%
  left_join(samples, by = "sample_id", relationship = "many-to-one")
stopifnot(!anyNA(joined$condition))
stopifnot(nrow(joined) == nrow(counts) * length(count_samples))

sample_qc <- joined %>%
  group_by(sample_id, condition) %>%
  summarise(
    total_counts = sum(raw_count),
    median_gene_count = median(raw_count),
    .groups = "drop"
  ) %>%
  mutate(total_counts_millions = total_counts / 1e6)

dir.create(here("results"), recursive = TRUE, showWarnings = FALSE)
write_tsv(sample_qc, out_table)
p <- ggplot(sample_qc, aes(x = condition, y = total_counts_millions, colour = condition)) +
  geom_point(size = 3) +
  labs(x = "Condition", y = "Sum of supplied counts (millions)",
       title = "Per-sample count totals") +
  theme_minimal() +
  theme(legend.position = "none")
ggsave(out_plot, plot = p, width = 6, height = 4, dpi = 150, bg = "white")
Check the tables and plot
The PNG is exported with an explicit white background so its dark labels remain readable in dark-background viewers. This changes the saved image background only, not the counts, scale or statistical meaning.
After the script finishes, confirm both files exist from the project root with file.exists(c("results/sample_qc.tsv", "results/reads_qc.png")) in R; both values should be TRUE. If either is FALSE, stop and check that the working directory is tidy-qc, the script completed without an error, and the output directory is writable.
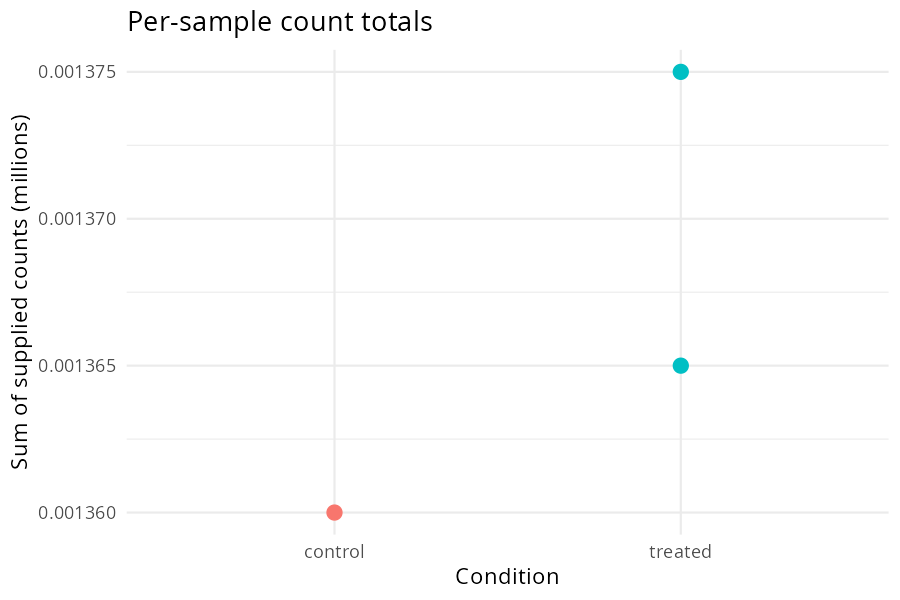
pivot_longer() makes one row for each gene-sample pair. For this three-gene, three-sample fixture, long_counts and joined each contain nine rows. The sample totals are 1,360, 1,375, and 1,365, respectively; the displayed values in millions are those totals divided by one million. The median gene counts are 320, 280, and 305. These values are arithmetic checks on the fixture, not expected results for a biological experiment.
Before interpreting the figure
- Confirm all three sample IDs appear exactly once in the output.
- Check that the plotted y-axis says supplied count totals in millions. This is not RPM; the script does not divide individual gene counts by a library-size denominator.
- Look for unexpectedly small or large totals relative to the study's own design and sequencing records. No universal cutoff is implied here.
What this QC can and cannot tell you
A per-sample sum can flag a possible library-size or data-import discrepancy. It does not establish why a sample differs, and total counts alone do not establish differential expression or other biological effects. Raw counts can be compared as a basic descriptive QC measure, but differential-expression workflows need appropriate normalization and statistical models that reflect the experiment and its variability. Do not use these totals as normalized expression values.
The original workflow called total_counts / 1e6 “RPM.” That calculation only expresses a total in millions; reads per million ordinarily describes a feature-level count divided by a sample-level library-size denominator and multiplied by one million. To avoid implying that this script computes normalized feature abundance, the code and plot now label the value as count totals in millions.
Diagnose common failures
- Missing or extra sample columns: the
setequal()check stops unless the count-column names and metadata IDs match exactly. Inspectsetdiff(count_samples, samples$sample_id)and the reverse comparison. Standardize whitespace or case only when the identifier source confirms that transformation is appropriate. - Duplicate metadata IDs: the uniqueness assertion stops before the join. A duplicated key can multiply gene-sample rows; correct or explain the metadata records rather than accepting inflated totals.
- Missing metadata after join:
stopifnot(!anyNA(joined$condition))catches unmatched or missing condition values. Check keys and missing condition values separately;left_join()preserves count rows while unmatched metadata fields become missing. - Counts fail validation: investigate blank values, text, non-finite values, or negative entries in the source file. A missing count is not interchangeable with zero, so do not replace missing values without a documented data-specific reason.
- Root or input path is wrong: check
getwd(), the local.herefile and the script location. Rerun the complete script fromtidy-qc;here::i_am()should resolve this lab even inside an ancestor Git repository. If you move or rename the script, update that declaration to match. - Output write fails: this script creates
results/, but permissions or an incorrect project root can still prevent writing. Inspecthere()and the exact output path.
R objects and data choices behind the script
Atomic vectors hold values of one basic type. A data frame stores columns of equal length, and a factor stores categorical values together with an explicit set and order of levels. Here the condition factor places control before treated in the plot; choose levels that reflect the study's intended display or model contrast rather than relying on alphabetical order.
Missing values (NA) represent unavailable or unrecorded observations; zero is a measured count of zero. Preserve the distinction while importing and decide how to handle missingness based on the data and analysis. Text formats such as TSV avoid some spreadsheet auto-formatting, but they still require inspection of imported column types and identifiers.
For reproducible work, record R and package versions with sessionInfo(). Larger datasets may need memory-aware tools or specialized Bioconductor workflows. Consult the package documentation and the relevant analysis method before extending this small teaching example.
Validation boundary
The fresh-install check began with a new Ubuntu 24.04.4 base filesystem without R or a reused R package library. The displayed system prerequisites installed R and its standard recommended packages from Ubuntu; the displayed R commands then compiled the lab packages from CRAN into the new project library. The installation check, separate fresh-process readiness check and complete workflow all exited successfully without an additional dependency repair or retry.
On that fresh installation, the full script produced the expected QC table, nine-row reshaped/joined objects and three-point plot. It rejected all 12 invalid-input cases without creating result files, accepted valid zero counts and reordered metadata, and recovered after correcting failed input. The 900 by 600 PNG had an opaque white background. These are checks on invented inputs, not biological validation.
This was minimal Ubuntu userspace in an isolated filesystem on the same Linux host, sharing its kernel. A full desktop VM, other operating systems and independent hardware remain untested.
What this run produced
This is the actual reads_qc.png saved by the R workflow above. The tiny count table and sample labels are invented teaching inputs, not experimental observations.
Run details and limits
The displayed setup and complete R workflow ran in a fresh project with R 4.3.3, tidyverse 2.0.0, dplyr 1.1.4, readr 2.1.5, here 1.0.1, and ggplot2 3.4.4 on Linux.
Checks confirmed the three sample totals, median supplied gene counts, output table, and opaque 900 by 600 PNG. All 12 deliberate invalid-input cases stopped as intended, and the documented recovery checks passed. No biological comparison is validated. Inspect the execution evidence.
References
Author: Nasir Mahmood Abbasi, PhD · Category: Foundations & Prerequisites